Freedom251 › AI video generators
HunyuanVideo
by HunyuanVideo
What HunyuanVideo is
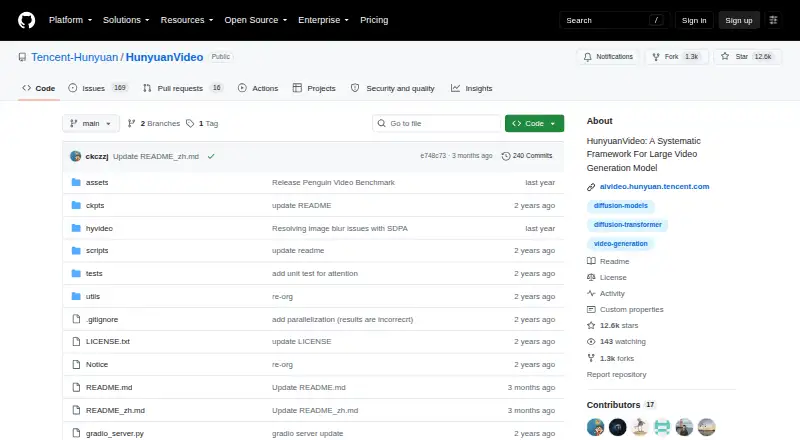
HunyuanVideo is an open-source video foundation model with PyTorch definitions, pretrained weights, and inference code for generating video from text or images. It supports text-to-video and image-to-video workflows, with listed maximum resolution of 1080p and commercial use permitted. The model has over 13 billion parameters and uses a decoder-only multimodal language model as its text encoder. Its unified architecture combines dual-stream and single-stream Transformer designs with full attention. Generation configurations include 540p and 720p at 129 frames. FP8 weights are available; the repository says they reduce GPU memory use by about 10GB. HunyuanVideo requires an NVIDIA CUDA GPU, with stated peaks of 60GB for 720p and 45GB for 544p generation. Linux is the tested operating system, with Docker images and an installation guide. Diffusers, xDiT parallel inference, and community ComfyUI tools are listed integrations.
Who it suits
It suits developers and creators who can run Linux-based, NVIDIA CUDA workflows and want open-source video generation. Commercial projects are permitted.
What it does well
- Open-source and free
- Supports text-to-video and image-to-video
- Commercial use is permitted
- Provides pretrained weights and inference code
- FP8 weights reduce stated memory needs
What to know first
- Requires an NVIDIA CUDA GPU
- Linux is the tested operating system
- No API access
- No AI avatar generation
Limits
The stated peak GPU memory requirement is 60GB for 720p 129-frame generation and 45GB for 544p 129-frame generation. Generation configurations are provided at 540p and 720p with 129 frames.
Getting started
- Open the HunyuanVideo GitHub repository
- Follow the Linux installation guide or use the provided Docker images
- Install on a system with an NVIDIA GPU and CUDA
- Download the inference code and pretrained weights
- Choose standard or FP8 weights based on available GPU memory
- Run text-to-video or image-to-video generation
Verdict
HunyuanVideo offers open-source generation with text and image inputs, commercial use, and community integrations. Its substantial GPU requirements and Linux-focused setup may limit suitable environments.
Questions
Is HunyuanVideo free?
Yes. It uses a free pricing model and is open source.
Which operating systems and hardware are supported?
Linux is the tested operating system. HunyuanVideo requires an NVIDIA GPU with CUDA.
Can it generate video from images?
Yes. It supports both image-to-video and text-to-video generation.
What resolution can it produce?
The listed maximum resolution is 1080p, with repository configurations at 540p and 720p using 129 frames.
Can businesses use HunyuanVideo?
Yes. Commercial use is permitted.
Does it offer an API or AI avatars?
No. API access and AI avatar generation are not provided.
Facts from HunyuanVideo's own pages
- AI avatars
- No · github.com, 19 Sept 2026
- API access
- No · github.com, 19 Sept 2026
- Architecture
- The model uses a unified image and video generative architecture with a hybrid dual-stream to single-stream Transformer design and full attention. · github.com, 11 Oct 2026
- Commercial use
- Yes · github.com, 19 Sept 2026
- Community tools
- The project lists community contributions including native ComfyUI support and a ComfyUI wrapper. · github.com, 11 Oct 2026
- Downloads
- The project provides inference code and pretrained model weights, with FP8 weights also available to reduce GPU memory use by about 10GB. · github.com, 11 Oct 2026
- Founded
- 1998 · github.com, 28 Sept 2026
- Generation
- The repository supports text-prompt video generation at 540p and 720p, with 129-frame configurations. · github.com, 11 Oct 2026
- Hardware requirements
- The model requires an NVIDIA GPU with CUDA; the stated peak GPU memory requirements are 60GB for 720p 129-frame generation and 45GB for 544p 129-frame generation. · github.com, 11 Oct 2026
- Headquarters
- Shenzhen, China · github.com, 28 Sept 2026
- Image-to-video
- The project links a separate HunyuanVideo image-to-video model with inference code and checkpoints. · github.com, 11 Oct 2026
- Integrations
- The repository says HunyuanVideo is integrated into Diffusers and offers parallel inference code powered by xDiT. · github.com, 11 Oct 2026
- License
- The repository links a license file, but the opened page does not state license terms in its displayed content. · github.com, 11 Oct 2026
- Lower-memory option
- FP8 quantized weights save about 10GB of GPU memory, according to the repository. · github.com, 11 Oct 2026
- Maker
- Tencent says it was founded in 1998 and is headquartered in Shenzhen, China. · tencent.com, 11 Oct 2026
- Maximum resolution
- 1080p · github.com, 19 Sept 2026
- Model size
- The model has over 13 billion parameters. · github.com, 11 Oct 2026
- Operating system
- Linux is the tested operating system, and the repository provides a Linux installation guide and Docker images. · github.com, 11 Oct 2026
- Product
- HunyuanVideo is an open-source video foundation model; the repository provides PyTorch model definitions, pretrained weights, and inference and sampling code. · github.com, 11 Oct 2026
- Prompt rewriting
- Its prompt rewrite model offers Normal and Master modes; the Master mode adds detail about composition, lighting, and camera movement and may lose some semantic details. · github.com, 11 Oct 2026
- Purpose
- HunyuanVideo is an open-source video foundation model with code and pretrained weights for video generation. · github.com, 11 Oct 2026
- Support
- The repository invites users to join its WeChat and Discord communities and to share projects using HunyuanVideo. · github.com, 11 Oct 2026
- Text encoder
- The model uses a decoder-only multimodal large language model as its text encoder. · github.com, 11 Oct 2026
- Text-to-video
- The released model generates videos from text prompts, with supported output settings up to 720p and 129 frames. · github.com, 11 Oct 2026
Where HunyuanVideo stands on Freedom251
- AI video generators#97 of 242
- AI Sound Effect Generators#17 of 29
- Text-to-Video Generators#14 of 23