Freedom251 › Statistical Analysis Software
partition
What partition is
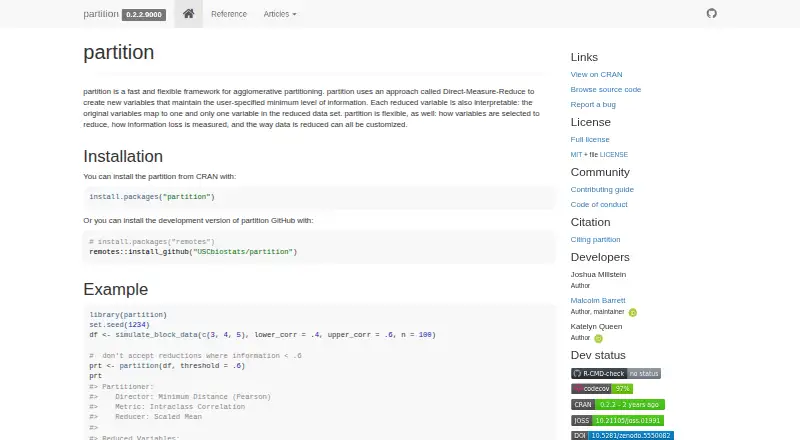
partition is a free Linux desktop R framework for agglomerative partitioning. It reduces a data frame to as few variables as possible while meeting a user-specified minimum information threshold. The method is aimed at highly correlated data, including genomic datasets with redundant features. Results remain interpretable: each reduced variable maps to one or more originals, and every original maps to exactly one reduced variable. Users can choose variable selection, information-loss measurement, and the reduction process, or create custom partitioners. Built-in methods use intraclass correlation, K-means, minimum R-squared, principal component 1, and standardized mutual information. Plotting functions return ggplots and support partition visualizations through ggplot2. Permutation testing compares observed statistics with permuted data, using 100 permutations by default. super_partition() divides large feature sets into clusters before processing, with a default maximum cluster size of 4000. Data import uses R data frames or tibbles. The MIT-licensed package installs from CRAN or GitHub.
Who it suits
partition suits R users working with correlated or high-dimensional data, especially genomic features. It is useful when reducing variables while retaining an explicit information threshold and interpretable mappings.
What it does well
- Free MIT-licensed package
- Custom partitioners supported
- Several built-in reduction methods
- Permutation testing included
- Handles large feature sets
What to know first
- Linux desktop deployment listed
- Requires R data frames or tibbles
- Performance varies by partitioning method
- Uses a default 4,000-feature cluster size
Verdict
partition offers configurable dimensionality reduction with mappings that remain easy to interpret. Its methods, plots, permutation tests, and large-feature handling make it suited to scripted R analysis rather than general desktop use.
Facts from partition's own pages
- Authors
- The site lists Joshua Millstein, Malcolm Barrett, and Katelyn Queen as developers, with Malcolm Barrett identified as maintainer. · uscbiostats.github.io, 12 Oct 2026
- Built-in methods
- Built-in partitioners include ICC, K-means, minimum R-squared, principal component 1, and standardized mutual information options. · uscbiostats.github.io, 12 Oct 2026
- Citation
- The site cites a 2020 Bioinformatics paper titled “Partition: A Surjective Mapping Approach for Dimensionality Reduction.” · uscbiostats.github.io, 11 Oct 2026
- Customizable
- Users can customize which variables are selected, how information loss is measured, and how data is reduced. · uscbiostats.github.io, 12 Oct 2026
- Customization
- Users can customize variable selection, how information loss is measured, and how data is reduced. · uscbiostats.github.io, 11 Oct 2026
- Custom partitioners
- Users can create custom partitioners from functions that select variables, measure information loss, and reduce data. · uscbiostats.github.io, 12 Oct 2026
- Data import formats
- R data frames/tibbles · uscbiostats.github.io, 23 Sept 2026
- Deployment
- desktop · uscbiostats.github.io, 23 Sept 2026
- Developers
- The site lists Joshua Millstein, Malcolm Barrett, and Katelyn Queen as developers and identifies Malcolm Barrett as maintainer. · uscbiostats.github.io, 11 Oct 2026
- Free plan
- Yes · uscbiostats.github.io, 23 Sept 2026
- Information threshold
- The partition() function reduces a data frame to as few variables as possible while meeting a user-specified information threshold. · uscbiostats.github.io, 12 Oct 2026
- Installation
- The package can be installed from CRAN or from the USCbiostats GitHub repository. · uscbiostats.github.io, 12 Oct 2026
- Interpretability
- Each original variable maps to exactly one variable in the reduced data set. · uscbiostats.github.io, 12 Oct 2026
- Large feature sets
- super_partition() handles data with many features by first dividing it into smaller clusters, with a default maximum cluster size of 4000. · uscbiostats.github.io, 12 Oct 2026
- License
- partition is released under the MIT license. · uscbiostats.github.io, 12 Oct 2026
- Methods
- Built-in partitioners include methods based on intraclass correlation, K-means, minimum R-squared, principal component 1, and standardized mutual information. · uscbiostats.github.io, 11 Oct 2026
- Performance
- The documentation reports benchmarking on a data frame with one million rows using a 2017 MacBook Pro with 16 GB RAM. · uscbiostats.github.io, 12 Oct 2026
- Permutation testing
- test_permutation() compares observed partition statistics with summaries from permuted data sets and defaults to 100 permutations. · uscbiostats.github.io, 12 Oct 2026
- Purpose
- partition is an R framework for agglomerative data reduction using a Direct-Measure-Reduce approach. · uscbiostats.github.io, 12 Oct 2026
- Scaling
- The site says the default ICC method scales more linearly than K-means methods as the number of columns exceeds the number of rows, while K-means is often faster at lower dimensions. · uscbiostats.github.io, 11 Oct 2026
- Scripting support
- Yes · uscbiostats.github.io, 23 Sept 2026
- Statistical tests
- Yes · uscbiostats.github.io, 23 Sept 2026
- Support
- The project directs users to GitHub to report bugs and provides contributor guidelines and a code of conduct. · uscbiostats.github.io, 12 Oct 2026
- Use case
- The package is particularly useful for highly correlated data, including genomic data with redundant features. · uscbiostats.github.io, 12 Oct 2026
Where partition stands on Freedom251
- Statistical Analysis Software#73 of 106