Freedom251 › Resume Parsing Software
OpenResumeParser
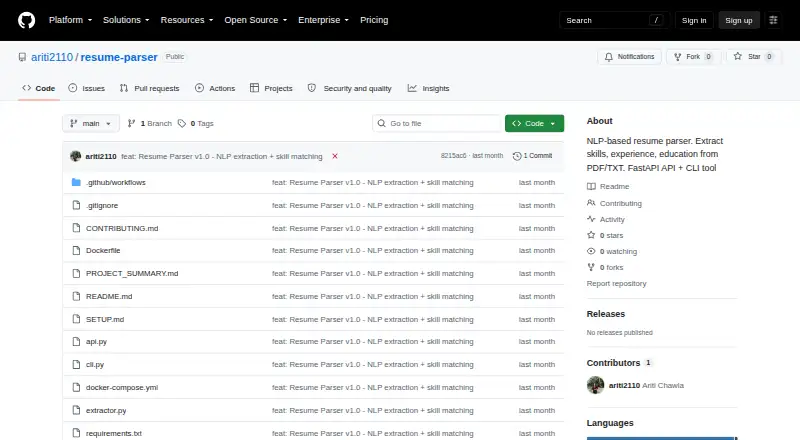
What OpenResumeParser is
OpenResumeParser extracts structured details from resumes and compares a candidate’s skills with a job description. It accepts PDF and TXT files and can identify names, email addresses, phone numbers, skills, experience and education. For skill matching, it returns a score, skills that match the job description, and skills that are missing. You can use it from a command line or through its FastAPI REST API, with batch processing also supported. Its curated database covers 120+ technical skills and can be customized in extractor.py. Docker and docker-compose files are included for deployment. The README describes the project as type-safe and says it uses Pydantic models. It is free under the MIT License for personal and commercial use, and its listed platforms are API, self-hosted and Windows. There are limits to the extraction: it cannot handle scanned PDFs or OCR, experience and education extraction is heuristic-based, and date extraction uses regular expressions. The skill database is curated rather than ML-based. Questions or bug reports can be raised through a GitHub issue.
Who it suits
It suits developers or teams that want to extract resume data and compare candidate skills with job requirements through a command-line tool or API. It may also suit users who want to self-host a free MIT-licensed project.
What it does well
- Parses resumes in PDF and TXT formats
- Offers command-line and FastAPI REST interfaces
- Returns match scores and matched or missing skills
- Curated database supports 120+ technical skills
- Includes Docker and docker-compose setup
What to know first
- Does not support scanned PDFs or OCR
- Experience and education extraction is heuristic-based
- Skill database is curated, not ML-based
- Date extraction uses regular expressions
Limits
The free MIT-licensed project has no OCR and does not process scanned PDFs. Experience and education extraction is heuristic-based; its skills database is curated, and dates are extracted with regular expressions.
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| MIT-licensed project | MIT license · personal and commercial use | Free |
As github.com lists them, read 7 Oct 2026. The maker's own page has the final word.
Getting started
- Open the project website on GitHub.
- Choose the command-line tool or FastAPI REST API.
- Deploy using the included Dockerfile and docker-compose setup, if needed.
- Use PDF or TXT resumes as input.
- Open a GitHub issue for questions or bug reports.
Verdict
OpenResumeParser combines resume field extraction with job-skill matching, and supports both command-line and API use. Scanned documents, OCR, and heuristic-based fields are important limitations to consider.
Questions
How much does OpenResumeParser cost?
The MIT-licensed project is free: free. The license permits personal and commercial use.
What resume formats does it accept?
It parses PDF and TXT files. Scanned PDFs are not supported, and the project has no OCR.
What information can it extract?
It extracts names, email addresses, phone numbers, skills, experience, and education.
How can I use it?
It provides a command-line tool and a FastAPI REST API. API access and batch processing are supported.
Is OpenResumeParser open source?
It is offered under the MIT License for personal and commercial use.
How can I get help?
The README directs users to open a GitHub issue for questions or bugs.
Facts from OpenResumeParser's own pages
- Deployment
- The project includes a Dockerfile and docker-compose setup. · github.com, 7 Oct 2026
- Extracted fields
- It extracts names, email addresses, phone numbers, skills, experience, and education. · github.com, 7 Oct 2026
- Input formats
- It parses resumes in PDF and TXT formats. · github.com, 7 Oct 2026
- Interfaces
- The project provides a command-line tool and a FastAPI REST API. · github.com, 7 Oct 2026
- License
- The project is offered under the MIT License for personal and commercial use. · github.com, 7 Oct 2026
- Notable limitations
- It does not support scanned PDFs or OCR, and experience and education extraction is heuristic-based. · github.com, 7 Oct 2026
- Other limitations
- The skills database is curated rather than ML-based, and date extraction uses regular expressions. · github.com, 7 Oct 2026
- Purpose
- The project extracts structured data from resumes and matches skills against job descriptions. · github.com, 7 Oct 2026
- Security and typing
- The README describes the project as type-safe and says it uses Pydantic models. · github.com, 7 Oct 2026
- Skill matching
- It compares resume skills with a job description and returns a match score, matched skills, and missing skills. · github.com, 7 Oct 2026
- Skill taxonomy
- The README says its curated skills database supports 120+ technical skills and can be customized in extractor.py. · github.com, 7 Oct 2026
- Support
- The README directs users to open a GitHub issue for questions or bugs. · github.com, 7 Oct 2026
Where OpenResumeParser stands on Freedom251
- Resume Parsing Software#7 of 32