Freedom251 › AI Music Generators
DiffRhythm
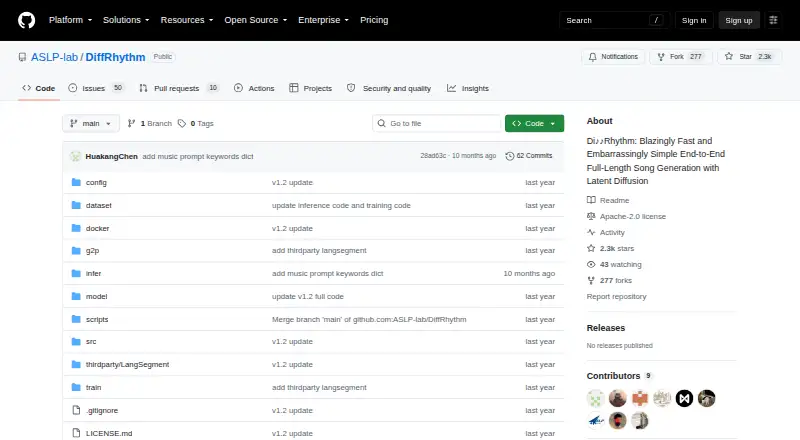
What DiffRhythm is
DiffRhythm is an open-source diffusion music model for generating full-length songs. It accepts text style prompts, supports instrumental creation, and can use a reference WAV file or text reference. Base models generate songs listed at 1 minute 35 seconds, while full models generate 4 minute 45 second songs. Version 1.2 adds song editing and continuation and improves handling of musical structure and style. Vocal generation and audio upload are supported, with WAV export for generated audio. The repository provides a Hugging Face Space and another project demo, plus local inference and Docker instructions for Linux, macOS, and Windows. DiffRhythm-base requires at least 8 GB of VRAM, with chunked decoding suggested as a way to meet that requirement. Code and DiT weights use Apache License 2.0. The project is intended for research, development, artistic creation, education, and entertainment. Training is described as coming soon, and users are advised to check originality, disclose AI involvement, and obtain permissions for protected styles.
Who it suits
It suits developers, researchers, educators, and creators exploring locally run music generation. Users should have suitable hardware or use the documented deployment options.
What it does well
- Open-source Apache 2.0 code and weights
- Generates songs from text or reference audio
- Supports instrumental and vocal generation
- Offers editing and continuation in version 1.2
- Local and Docker deployment instructions
What to know first
- Base model requires at least 8 GB VRAM
- Training code is coming soon
- Generated base songs are 1 minute 35 seconds
- Responsible use requires originality and permissions checks
Verdict
DiffRhythm offers multiple input modes, song editing, and local deployment across major desktop systems. Hardware requirements and the unfinished training component matter when planning development or production use.
Facts from DiffRhythm's own pages
- Audio export formats
- wav · github.com, 21 Sept 2026
- Audio upload
- Yes · github.com, 21 Sept 2026
- Commercial use
- Yes · github.com, 21 Sept 2026
- Demo
- The project links to a Hugging Face Space demo and a separate project demo page. · github.com, 12 Oct 2026
- Deployment
- The README documents local inference and Docker deployment, including setup instructions for Linux, macOS, and Windows. · github.com, 12 Oct 2026
- Editing
- The project says version 1.2 enables song editing and continuation and improves its handling of music structure and style. · github.com, 12 Oct 2026
- Hardware requirement
- DiffRhythm-base requires at least 8 GB of VRAM; the repository says chunked decoding can help meet this requirement. · github.com, 12 Oct 2026
- Input modes
- The project describes text-based style prompts, instrumental generation, and generation using a reference WAV file. · github.com, 12 Oct 2026
- Inputs and modes
- It supports text-based style prompts, instrumental generation, and inference using a reference WAV or a text prompt reference. · github.com, 12 Oct 2026
- Installation
- The repository provides local inference instructions for Linux, macOS, and Windows, and includes Docker installation instructions. · github.com, 12 Oct 2026
- Intended users
- The project describes itself as a foundation for research and development and says it supports artistic creation, education, and entertainment. · github.com, 12 Oct 2026
- License
- The code and DiT weights are released under Apache License 2.0, which allows use, modification, and distribution subject to its notices and disclaimer. · github.com, 12 Oct 2026
- Pricing
- The project says its makers do not make a profit from the model; the page lists no paid plans or prices. · github.com, 12 Oct 2026
- Purpose
- DiffRhythm is an open-source diffusion music model designed to generate full-length songs. · github.com, 12 Oct 2026
- Responsible use
- The makers advise users to verify musical originality, disclose AI involvement, and obtain permissions when adapting protected styles. · github.com, 12 Oct 2026
- Song length
- The listed base models generate 1 minute 35 second songs, and the full models generate 4 minute 45 second songs. · github.com, 12 Oct 2026
- Support
- The repository invites messages to the research team at [email protected]. · github.com, 12 Oct 2026
- Training
- The repository says training is coming soon. · github.com, 12 Oct 2026
- Training code
- The README lists training as coming soon. · github.com, 12 Oct 2026
- Vocal generation
- Yes · github.com, 21 Sept 2026
- What it does
- DiffRhythm is an open-source diffusion model for generating full-length songs. · github.com, 12 Oct 2026
Where DiffRhythm stands on Freedom251
- AI Music Generators#56 of 123