Freedom251 › AI Song Cover Generators
Diff-SVC
What Diff-SVC is
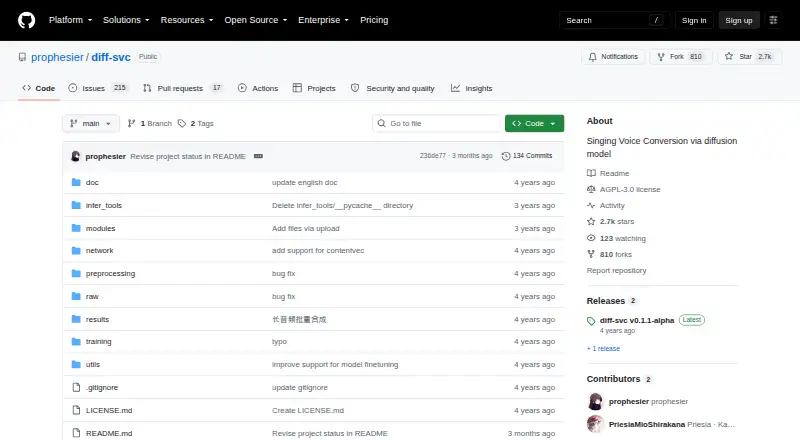
Diff-SVC is a free, open-source singing voice conversion project for Linux, Windows, and self-hosted use. It transforms an input singing voice toward a target timbre and provides basic pitch correction using diffusion models. Inference runs through the included notebook, with support for most input and output formats, including OGG, and recorded support for 44.1 kHz audio. Long recordings are automatically sliced, and support files are available for real-time conversion inference. Users can train models from a configuration file and experiment name, including on custom datasets. Single-speaker training is supported, with guidance recommending at least three hours of dry vocals from the target speaker; the guide says full inference can run on a 6 GB GTX 1060 GPU. Listed export formats are WAV and FLAC. The project supports vocal uploads and custom voice creation but not instrumental uploads. It uses the AGPL-3.0 license, restricts commercial use, and is intended for academic exchange rather than production. The repository says it is no longer actively maintained and directs English support to Discord.
Who it suits
It suits researchers, hobbyists, and developers exploring singing voice conversion in self-hosted environments. Users should be comfortable with notebook-based inference and model training.
What it does well
- Free and open source under AGPL-3.0
- Custom dataset and single-speaker training
- Automatic slicing for long audio
- WAV and FLAC export formats
- Real-time conversion support files
What to know first
- No instrumental upload support
- Commercial use is restricted
- No longer actively maintained
- Not intended for production environments
Verdict
Diff-SVC provides a configurable, self-hosted route to singing voice conversion with training and real-time resources. Its maintenance status, academic focus, and commercial restriction are important limitations for production or commercial projects.
Facts from Diff-SVC's own pages
- Attribution
- The maker asks users who redistribute the code or publicly publish results to credit the original author and repository. · github.com, 9 Oct 2026
- Audio formats
- The training guide says data preparation supports WAV and Ogg audio. · github.com, 9 Oct 2026
- Audio sample rates
- The README records support for 44.1 kHz audio. · github.com, 9 Oct 2026
- Custom datasets
- The project supports training on custom datasets. · github.com, 9 Oct 2026
- Dependencies
- The README credits DiffSinger, the OpenVPI-maintained DiffSinger version, and Soft-VC as project bases. · github.com, 9 Oct 2026
- Inference
- Inference is available through the included inference.ipynb notebook or infer.py script. · github.com, 9 Oct 2026
- Integrations
- The maker identifies DiffSinger, the OpenVPI-maintained DiffSinger version, and soft-vc as project foundations. · github.com, 9 Oct 2026
- Intended use
- The project says it is for academic exchange and is not intended for production environments. · github.com, 9 Oct 2026
- License
- The repository identifies its license as AGPL-3.0. · github.com, 9 Oct 2026
- Long audio
- Inference automatically slices audio longer than 30 seconds at silences. · github.com, 9 Oct 2026
- Maintenance
- The project is no longer actively maintained, and its README describes it as an early exploration of diffusion models for singing voice conversion. · github.com, 9 Oct 2026
- Method
- The project describes itself as singing voice conversion via diffusion models. · github.com, 9 Oct 2026
- Performance
- The guide says full inference can run on a 6 GB GTX 1060 GPU. · github.com, 9 Oct 2026
- Purpose
- Diff-SVC converts input singing voices into a target timbre and supports basic pitch correction. · github.com, 9 Oct 2026
- Real-time conversion
- The README mentions support files for real-time voice conversion inference. · github.com, 9 Oct 2026
- Redistribution
- The README asks users who redistribute the code or publicly publish results to credit the original author and repository. · github.com, 9 Oct 2026
- Security
- The repository page displays no reported security advisories in its Security and quality section. · github.com, 9 Oct 2026
- Support
- The README points users to a Discord for English support. · github.com, 9 Oct 2026
- Training
- The README provides a command to train a model using a configuration file and a user-supplied experiment name. · github.com, 9 Oct 2026
- Training data
- The guide supports single-speaker training and recommends at least three hours of target-speaker dry vocals. · github.com, 9 Oct 2026
Where Diff-SVC stands on Freedom251
- AI Song Cover Generators#22 of 56