Freedom251 › Text-to-Speech Software
Confucius4-TTS
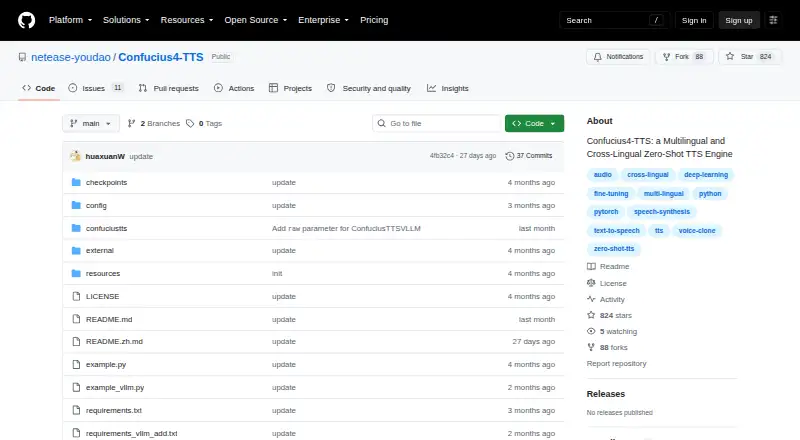
What Confucius4-TTS is
Confucius4-TTS is a free, open-source text-to-speech engine for multilingual and cross-lingual speech generation. It supports 14 languages and can synthesize another supported language while retaining the identity of a reference speaker. Emotion transfer is listed as a feature for carrying the feeling of a reference voice into generated speech. A browser-based Gradio interface accepts reference audio, text, and a selected language. The project also provides a FastAPI server with streaming and non-streaming endpoints. Non-streaming requests return WAV files; streaming requests return raw int16 little-endian PCM chunks and provide the sample rate in a response header. Training pipelines are documented for the Text2Semantic and Semantic2Acoustic modules. Installation requirements list Python 3.10 and CUDA 12.6. The repository includes an Apache License, Version 2.0, permits commercial use, and documents API, Linux, self-hosted, and web deployment. A vLLM backend targets version 0.16.0 with the V1 engine, although hardware and CUDA requirements may prevent it from running. NetEase Youdao is identified as the maker.
Who it suits
Confucius4-TTS suits developers needing self-hosted or API speech synthesis across 14 languages. It also fits projects requiring speaker-identity retention, emotion transfer, streaming output, or commercial use.
What it does well
- Supports 14 languages
- Retains speaker identity across languages
- Offers Gradio and FastAPI interfaces
- Provides WAV and PCM output
- Commercial use is permitted
What to know first
- Requires Python 3.10 and CUDA 12.6
- vLLM support targets version 0.16.0
- Hardware requirements may prevent vLLM running
- Setup includes documented training pipelines
Verdict
Confucius4-TTS offers open-source multilingual synthesis with cross-language voice identity and streaming APIs. Its Python, CUDA, and hardware requirements should be checked before deployment.
Facts from Confucius4-TTS's own pages
- API
- A FastAPI server provides non-streaming and streaming TTS endpoints that accept text, a language code and a reference audio upload. · github.com, 13 Oct 2026
- API access
- Yes · github.com, 20 Sept 2026
- API output
- The non-streaming API returns a WAV file and the streaming API returns raw int16 little-endian PCM chunks. · github.com, 12 Oct 2026
- Commercial use
- Yes · github.com, 20 Sept 2026
- Cross-language transfer
- The project says users can synthesize speech across its supported languages while retaining the same voice. · github.com, 13 Oct 2026
- Cross-lingual transfer
- It can synthesize speech across its supported languages while retaining speaker identity. · github.com, 12 Oct 2026
- Deployment
- The repository provides a Gradio web UI and a FastAPI server with streaming and non-streaming endpoints. · github.com, 12 Oct 2026
- Emotion
- The README describes emotion transfer as a feature. · github.com, 12 Oct 2026
- Emotion transfer
- The listed features include emotion transfer that aims to carry the feeling of a reference voice into generated speech. · github.com, 13 Oct 2026
- Export formats
- WAV,PCM · github.com, 20 Sept 2026
- Fine-tuning
- The README documents training workflows for its Text2Semantic and Semantic2Acoustic modules using prepared TSV training data and pretrained models. · github.com, 13 Oct 2026
- Integrations
- The project acknowledges use of Qwen3-TTS, CosyVoice, Amphion/MaskGCT, w2v-BERT 2.0, Seed-VC, and BigVGAN components or methods. · github.com, 12 Oct 2026
- Languages
- 14 · github.com, 20 Sept 2026
- Languages
- The project lists support for 14 languages: Chinese, English, Japanese, Korean, German, French, Spanish, Indonesian, Italian, Thai, Portuguese, Russian, Malay and Vietnamese. · github.com, 13 Oct 2026
- License
- The repository includes an Apache License, Version 2.0. · github.com, 13 Oct 2026
- Limit
- The README says vLLM support currently targets version 0.16.0 with the V1 engine and warns that hardware and CUDA requirements may prevent it from running. · github.com, 12 Oct 2026
- Maker
- The GitHub organization identifies itself as NetEase Youdao and lists Beijing as its location. · github.com, 13 Oct 2026
- Performance
- The README reports multilingual and cross-lingual benchmark results, including WER, CER, and speaker similarity metrics. · github.com, 12 Oct 2026
- Platforms
- web,api,linux,self_hosted · github.com, 20 Sept 2026
- Product
- Confucius4-TTS is an LLM-based multilingual and cross-lingual zero-shot text-to-speech engine. · github.com, 12 Oct 2026
- Purpose
- Confucius4-TTS is an LLM-based text-to-speech system for multilingual and cross-lingual speech synthesis that preserves speaker identity across languages. · github.com, 13 Oct 2026
- Requirements
- The listed installation requirements are Python 3.10 and CUDA 12.6. · github.com, 13 Oct 2026
- Streaming
- The project documents streaming generation that returns raw int16 little-endian PCM chunks and provides the sample rate in a response header. · github.com, 13 Oct 2026
- vLLM support
- For faster Text2Semantic generation, the README documents a vLLM backend and says it currently supports vLLM 0.16.0 with the V1 engine. · github.com, 13 Oct 2026
Where Confucius4-TTS stands on Freedom251
- Text-to-Speech Software#186 of 223
- Text-to-speech tools#200 of 232