The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Debug embedded Linux by starting with the failure and the evidence you can collect—not by reaching first for a debugger. Use boot logs and persistent records when the device cannot be stopped; use strace for system-call boundaries, GDB for userspace source debugging, ftrace or perf for kernel behavior and performance, and KGDB, crash dumps, or JTAG only when simpler observation is not enough. The right choice depends on whether the fault is in the boot chain, kernel, driver, service, application, or hardware—and whether you can safely reproduce it.
Choose a tool by failure class
Embedded Linux debugging spans several layers: boot ROM and bootloader; kernel and modules; init system and services; applications and libraries; device tree and hardware configuration; and the physical board and peripherals. A userspace debugger cannot explain a boot ROM failure, while a kernel debugger is usually the wrong first tool for a missing file or permission error.
| Symptom | Start with | Escalate to |
|---|---|---|
| No boot or no console | UART capture, bootloader output, reset reason, kernel command line, persistent logs | Early printk/KGDB, JTAG/OpenOCD, logic analyzer |
| Application or service crash | Service logs, core dump, strace |
Host GDB with gdbserver, sanitizers |
| Wrong file, socket, permission, or syscall behavior | strace, /proc, service-manager logs, dmesg |
perf trace, security-policy and filesystem analysis |
| Driver or kernel malfunction | dmesg, dynamic debug, subsystem status |
ftrace/tracepoints, KGDB, crash dump |
| Kernel panic or oops | Serial log, pstore, panic signature, matching symbols | kdump, crash, KGDB, JTAG |
| CPU load or latency | top, /proc, perf stat |
perf record, ftrace, trace-cmd |
| Race, memory corruption, or field-only reset | Persistent logs, watchdog/reset reason, trace buffers | KCSAN/KASAN or other test-image instrumentation, kdump, hardware trace |
The Linux kernel’s debugging guidance treats these techniques as complementary. A useful rule is to observe first and attach a live debugger only when the evidence cannot answer the question. A breakpoint stops execution; that can stop watchdog servicing, alter interrupt behavior, or hide a timing-sensitive race. Logging can perturb timing too, so tracing is often a better next step.
First decide what access you have
- Local shell: inspect logs, processes, filesystems, memory, and interfaces; use
strace,perf, or tracefs if installed and enabled. - Serial console: capture bootloader and kernel output, especially when networking is unavailable. Check board voltage levels and wiring; a serial adapter is not automatically electrically compatible.
- SSH/network: collect evidence remotely, but consider whether attaching or copying a large dump risks disconnecting or overloading the failing device.
- Recovery shell or initramfs: useful for mount, root-filesystem, and startup failures; include the drivers and tools needed for diagnosis.
- Can replace the image or rebuild the kernel: add symbols, tracing, sanitizers, or KGDB to a controlled development image.
- Only production access, cannot stop the target: prioritize persistent logs, pstore/ramoops, reset-reason records, core dumps, telemetry, and preconfigured trace buffers.
- JTAG/SWD probe available: consider it for pre-Linux faults, severe hangs, or a broken console, subject to SoC support and debug-lock policy.
- Reproducible QEMU setup: use it to investigate software paths, while remembering it does not reproduce the board’s power, timing, DMA, clock, electrical, or peripheral behavior.
KGDB needs a kernel configured for it and a supported I/O transport; it is not a universal production diagnostic mechanism. The KGDB documentation describes its configuration and transport requirements.
#1 Best Overall
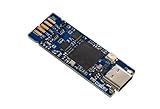
- Tiny 15 mm × 42 mm standalone debugging and programming probe for STM32 microcontrollers Self‑powered through a USB Type-C connector USB 2.0 high-speed interface Probe firmware update through USB Optional drag‑and‑drop Flash memory programming of binary files Communication bi-color LED JTAG communication support up to 21 MHz SWD (Serial Wire Debug) and SWV (Serial Wire Viewer) communication support up to 24 MHz Virtual COM port (VCP) up to 15 Mbps 1.65 to 3.60 V ap
- Board connectors:– USB Type-C connector– 1.27 mm pitch STDC14 debug connector with STDC14 to STDC14 flat cable– 2.0 mm pitch on-board pads for BTB (Board-to-board) card edge connector
Prepare a debuggable image before a failure
Keep the deployable target small if needed, but retain the exact artifacts that let you interpret its behavior. A useful archive contains:
- The exact target executable and matching unstripped executable with DWARF information.
- Matching shared libraries, kernel
vmlinux, and module files (.ko) with symbols. - Source revision and generated files, build ID, compiler/linker versions, architecture and ABI.
- Kernel configuration, device-tree source and deployed blob, and image/root-filesystem version.
- Build metadata sufficient to distinguish this artifact from a rebuild with different flags, configuration, or toolchain.
“Same source” is not enough: compiler flags, generated code, link order, configuration, and library versions affect addresses and symbols. A mismatched symbol file can point to plausible but wrong source. Keep debug information on the host or in a controlled symbol store rather than assuming it belongs in a production root filesystem; symbols consume storage and can reveal implementation details.
Yocto/OE builds can produce debug packages and SDK artifacts for host-side analysis; retain the matching outputs for the deployed image. The Yocto documentation describes debug-package and SDK workflows. Exact package names and layouts depend on the release and configuration. Similar principles apply to Buildroot and other build systems.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Establish a baseline and preserve logs
Record a baseline early, before changing the system or enabling noisy diagnostics:
uname -a
cat /proc/cmdline
cat /proc/version
dmesg
cat /proc/uptime
cat /proc/interrupts
cat /proc/meminfo
mount
df -h
ps
ip addr
Then follow the kernel ring buffer or inspect the current boot and service logs:
dmesg -w
dmesg -T
journalctl -b
journalctl -u <service>
dmesg -T attempts to render timestamps as wall-clock time; for correlation, note that wall-clock time may be unset or adjusted early in boot. Preserve boot identity, uptime/monotonic timing, firmware and hardware revision, boot count, environment, and reset reason. An isolated error line is much less useful than the preceding events and the first failure.
Not every embedded image uses systemd. On a minimal image, inspect the kernel ring buffer, BusyBox logread, available files under /var/log, a captured UART session, network logging, and any bootloader reset registers. Ring buffers are finite and can overwrite the earliest evidence. If the device reboots before logs can be collected, set up persistence before reproducing the fault.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsDebugging userspace processes
Use strace to find a failing boundary
Choose strace when you need to know which file, device, socket, or syscall a process uses; why a permission or path lookup fails; or whether it is waiting in poll, epoll, futex, or an ioctl. It reveals interactions with the kernel, not necessarily the root cause inside the program or driver. The kernel’s userspace debugging guide also recommends tracing a process to inspect its kernel interactions.
strace -f -tt -T -o /tmp/myapp.strace /usr/bin/myapp
strace -f -p <PID>
strace -f -e trace=file,network -p <PID>
strace -tt -T -p <PID>
-f follows children and threads but can produce a great deal of output; -tt adds timestamps and -T reports syscall duration. Start with a narrow syscall filter if the target has limited CPU or storage. Tracing every call can alter timing and generate large files.
Use host GDB with gdbserver for source-level application debugging
The target runs the program under gdbserver; the development host runs the full GDB and supplies symbols. The target needs a compatible server and a way to communicate. The host needs the exact unstripped executable and matching libraries/sysroot. Confirm architecture, ABI, endianness, and library layout.
# Target
 gdbserver :2345 /usr/bin/myapp arg1 arg2
# Host
gdb /path/to/unstripped/myapp
(gdb) set sysroot /path/to/target-rootfs
(gdb) target remote <target-ip>:2345
(gdb) break main
(gdb) continueTo attach to an existing process, run gdbserver :2345 --attach <PID> on the target and connect from host GDB with target remote <target-ip>:2345. The GDB server documentation explains the split: the server runs on the target, while host GDB handles symbols and debugging.
Quick wins for a faster PC:
Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Clear out junk files and repair common Windows errorsFree Scan →Useful commands after stopping at a fault include:
(gdb) set pagination off
(gdb) bt full
(gdb) info threads
(gdb) thread apply all bt full
(gdb) info registers
(gdb) frame 0
(gdb) list
(gdb) print variable
(gdb) x/32gx address
(gdb) disassemble /m function
(gdb) watch variable
Watchpoints are limited by hardware and target support. GDB can also catch syscalls, but for broad syscall diagnosis strace is often simpler.
Common failures: “No symbol table is loaded” usually means the wrong or stripped executable; missing shared-library symbols usually indicate an incorrect sysroot. A breakpoint that never hits may reflect the wrong binary, optimized-out code, a path not taken, library load timing, PIE/ASLR relocation, or an incorrect breakpoint location. “Cannot access memory” can mean the process exited or the address/context is invalid. A remote communication error often points to a blocked port, stale server, wrong serial device, or a target reset. Optimized builds can report variables as <optimized out>; a debug build may behave differently because of altered timing and layout.
Use core dumps for postmortem application failures
Core dumps preserve process memory at a crash and can be analyzed after the target has recovered. Check the shell limit and handler rather than assuming dumps are enabled:
ulimit -c unlimited
cat /proc/sys/kernel/core_pattern
On systemd systems, core handling may go through systemd-coredump; elsewhere the kernel’s core_pattern determines the destination or handler. These behaviors vary by distribution and init system. Analyze with the exact executable, libraries, and symbols:
gdb /path/to/unstripped/myapp /path/to/core
(gdb) thread apply all bt full
(gdb) info registers
(gdb) frame 0
(gdb) list
Storage limits, permissions, set-user-ID behavior, and security policy can prevent a dump from being written. Core files may contain credentials, keys, user data, and other secrets. Define size limits, retention, encryption, access control, and deletion policy before enabling dumps in the field.
Rank #2

- [EFFICIENT AND PRACTICAL] - Quickly convert and adapt to different debugging tools to improve equipment commissioning efficiency
- [WIDE ADAPTATION] - Conveniently debug different types of products by supporting multiple device interfaces
- [MULTI FUNCTIONAL] - meet the needs of different working environments with multiple mode conversion
- [EASY TO USE] - Simple setup, no additional software or drivers required for stable and reliable equipment debugging
- [ ] - High stability ensures and efficient equipment debugging
Diagnose kernel and driver behavior
Read the first kernel failure, not just the last message
An oops is a kernel fault report; a panic halts or restarts the system according to configuration. Read the faulting instruction pointer (RIP or PC), call trace, module and offset, process/context, and any taint markers. A NULL-pointer message identifies a faulting access, but the corruption or invalid state may have originated earlier. Workqueue, interrupt, and softirq context matter because sleeping and locking rules differ by context. Lockdep and sanitizer reports can reveal an earlier or more specific violation than a later panic.
For a symbolized offset such as my_driver_function+0x50/0x138 [my_driver], use the exact matching build artifacts. With kernel debug information, the kernel script can map addresses to source:
scripts/faddr2line path/to/module.ko my_driver_function+0x50/0x138Disassembly is an alternative when source mapping is unavailable, though without symbols it may show only assembly:
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minutePC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11aarch64-linux-gnu-objdump -dS path/to/module.koThe kernel’s bug-hunting guide covers decoding reports; faddr2line needs suitable debug information.
Turn on dynamic debug selectively
Dynamic debug enables existing pr_debug(), dev_dbg(), and related call sites. It cannot create logging sites that were not compiled into the code. Check support and available controls:
test -e /proc/dynamic_debug/control && echo available
cat /proc/dynamic_debug/control
Enable by file, function, or module, then disable when finished:
echo 'file drivers/foo/bar.c +p' > /proc/dynamic_debug/control
echo 'func foo_probe +p' > /proc/dynamic_debug/control
echo 'module foo +p' > /proc/dynamic_debug/control
# Cleanup
echo 'file drivers/foo/bar.c -p' > /proc/dynamic_debug/control
Support typically requires CONFIG_DYNAMIC_DEBUG, or an appropriate CONFIG_DYNAMIC_DEBUG_CORE arrangement for selected modules. Controls can match filenames, functions, lines, modules, formats, or classes. Kernel log-level filtering can still hide messages; procfs/debugfs access may be restricted. Excessive output can flood a serial link, overwrite useful logs, expose sensitive information, or change timing. See the versioned dynamic debug documentation; availability and paths depend on the kernel configuration.
Recommended Free Tools
Use ftrace and tracefs for kernel control flow and events
ftrace is kernel tracing infrastructure, not simply another print function. Depending on configuration, it can record function entry/exit, tracepoints, scheduler activity, IRQs, softirqs, and subsystem events. Mount tracefs if it is available but not mounted:
mount -t tracefs tracefs /sys/kernel/tracing
cd /sys/kernel/tracing
echo 0 > tracing_on
echo nop > current_tracer
echo function_graph > current_tracer
echo my_driver_function > set_graph_function
echo 1 > tracing_on
# Reproduce the behavior
echo 0 > tracing_on
cat trace
For event tracing, choose events that answer the question rather than enabling everything:
echo 0 > tracing_on
echo 'sched:*' > set_event
echo 1 > tracing_on
# Reproduce
echo 0 > tracing_on
cat trace
The available event names and tracers vary by kernel and configuration; inspect available_events and related tracefs files. trace presents the buffered trace for inspection; trace_pipe streams and consumes events as they are read. trace-cmd and KernelShark can help collect and visualize data, at the cost of additional packages and deployment complexity. The kernel’s debugging guide documents tracefs controls and tracers.
Unrestricted printk() can change scheduling, overwhelm logs, and hide the first failure. trace_printk() writes to the tracing buffer and can be less disruptive, but it is still instrumentation, not free observation. The driver debugging guide discusses its use and cautions.
Free tools Windows power users keep installed
One-click scans. No signup required.
When done, restore normal tracing state:
echo 0 > tracing_on
echo nop > current_tracer
echo > set_ftrace_filter
echo > set_event
Exact controls vary with kernel version; preserve existing settings if the system already uses tracing.
Inspect device tree, power, clocks, and the board
Not every driver symptom is a software defect. Check whether the running device tree describes the actual board and whether the required resources are enabled and routed correctly. Depending on configuration and mount points, useful inspection points include:
cat /proc/device-tree/model
find /sys/firmware/devicetree/base -maxdepth 2 -type f
cat /proc/interrupts
cat /sys/kernel/debug/clk/clk_summary
cat /sys/kernel/debug/regulator/regulator_summary
The clock and regulator summaries generally require debugfs and relevant kernel support; they are not guaranteed to exist. Investigate incompatible or disabled nodes, GPIO polarity, regulator supply, clock rate/parent, DMA address width and cache coherency, interrupts, pinmux, power sequencing, reset lines, device-tree overlays, and thermal throttling. For a bus or peripheral problem, correlate kernel evidence with an oscilloscope, logic analyzer, bus analyzer, or the vendor’s register documentation. Electrical levels and signal integrity can masquerade as random software failures.
Measure performance and timing
Use perf when the question is quantitative: which code consumes CPU, whether the system is context-switching excessively, or whether page faults and scheduling contribute to latency. Examples:
perf stat -d ./myapp
perf stat -p <PID>
perf record -g -p <PID> -- sleep 10
perf report
perf top
perf trace -p <PID>
perf stat -d can report task clock, context switches, migrations, page faults, cycles, instructions, branches, and branch misses where supported. Use perf record and perf report to locate sampled hot paths. Performance-counter availability depends on architecture, SoC implementation, kernel support, and permissions; embedded PMUs may expose incomplete or vendor-specific data. Call stacks require usable frame pointers, DWARF unwinding, or compatible unwind support. Minimal production images may omit perf tools, so collect on a test image or use an SDK where possible. Without symbols, perf trace may show raw addresses rather than useful names; see the perf trace manual.
Rank #3

- Supports many targets, including Raspberry Pi Pico
- Open Source and Open Hardware, Based on Black Magic Probe
- Built In Voltage Translator
- Raspberry Pi: RP2040
- Atmel: SAMD20, SAMD21, SAM32, SAM3X, SAM3S, SAM3U, SAM4L, SAM4S
For a deterministic sequence—such as an interrupt arriving, a task waking, and a driver callback running—ftrace events may be more useful than statistical samples. For a hotspot, perf is often stronger. Both add overhead, and high event rates can fill buffers or consume CPU.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Use sanitizers and verification tools in test builds
Sanitizers can expose classes of bugs that ordinary tracing cannot, but they generally belong in a controlled development or test image, not automatically in production. Check support for the architecture, kernel version, compiler, and target resources before planning around one:
- KASAN: detects many kernel memory-safety errors, with substantial memory and runtime cost.
- KMSAN: targets uninitialized-memory use and has demanding build/runtime requirements.
- KCSAN: samples for data races and is useful for concurrency investigation, but does not guarantee a race will be reproduced.
- KFENCE: lower-overhead, probabilistic detection of selected heap errors.
- kmemleak: helps identify selected kernel memory leaks.
- lockdep: detects locking dependency problems and potential deadlocks.
- UBSAN: checks selected undefined behavior.
- AddressSanitizer/UndefinedBehaviorSanitizer: can help userspace code when the toolchain and target resources support them.
- Valgrind: useful for some userspace memory investigations, but often too resource-intensive for small embedded targets.
These tools can change memory layout, timing, resource use, or scheduling. A clean instrumented run does not prove the field problem is absent, and an instrumented failure may not match production behavior.
Escalate to kernel debugging only when needed
KGDB and KDB
KDB provides console-oriented inspection and control; KGDB connects the kernel to host GDB for source-level debugging. A typical KGDB build needs CONFIG_KGDB, a supported I/O option such as CONFIG_KGDB_SERIAL_CONSOLE, and CONFIG_DEBUG_INFO. CONFIG_FRAME_POINTER can improve backtrace reliability, but is not mandatory in every configuration. Use the matching symbol-rich vmlinux on the host—not the compressed boot image such as bzImage, zImage, or uImage. The KGDB documentation covers configuration and architecture considerations.
A serial setup may use a kernel command line such as kgdboc=ttyS0,115200, but the device name, transport, baud rate, and voltage are board-specific. To stop early in boot, a setup may use:
kgdboc=ttyS0,115200 kgdbwaitkgdbwait requires the KGDB I/O driver to be built into the kernel and configured on the command line; a loadable-only driver cannot provide the expected early wait. Host GDB usually loads vmlinux and connects using the transport-specific target syntax, for example:
gdb /path/to/vmlinux
(gdb) set architecture <target-architecture>
(gdb) target remote /dev/ttyUSB0
(gdb) info threads
(gdb) bt
That device path and syntax are examples, not universal instructions. Some kernel builds include helper commands such as lx-dmesg and lx-ps; availability depends on GDB scripts and build configuration.
KGDB may contend with a serial console sharing the same UART. Incorrect wiring, baud rate, unsupported architecture, missing symbols, read-only kernel text protections, or a target that is not actually stopped can prevent useful debugging. The debugger may halt all CPUs and let a watchdog reset the board. A live kernel debugger changes system behavior and can destroy evidence, so use it when interactive inspection is worth the disruption.
JTAG, SWD, and OpenOCD
JTAG or SWD is valuable when Linux never reaches a usable console, a fault occurs before kernel initialization, interrupts are disabled, the serial path is broken, or reset/clock/memory-controller behavior needs examination. OpenOCD can connect supported adapters and targets to GDB’s remote debugging interface; it is not a universal driver for every probe or SoC.
Compatibility depends on CPU debug architecture, SoC implementation, adapter, OpenOCD target configuration, reset wiring, board routing, voltage, and secure-debug policy. Debug pins may be inaccessible or fused/locked on production hardware. Secure boot and debug-lock settings can restrict access. Confirm the exact board and silicon support before buying or configuring a probe.
Open-source GDB, ftrace, perf, KGDB, and OpenOCD cover many workflows without a commercial purchase. A compatible hardware probe can be worthwhile for board bring-up or pre-OS faults; professional suites may make sense for complex multicore products or supported trace workflows. Choose based on architecture/protocol, target support, multicore and trace needs, reset behavior, connector/pinout, and licensing—not on a generic promise that one debugger can solve every fault.
Preserve kernel failures for postmortem analysis
pstore, ramoops, and tracing buffers
Persistent storage for panic output can be more practical than a live debugger on a field device. pstore can expose records from supported backends; ramoops uses reserved RAM to retain records across a reset, subject to platform configuration. Confirm the backend, reserved-memory region, boot-time behavior, and whether later boots overwrite the evidence. Record reset reason and boot count alongside the log.
A circular ftrace buffer can preserve events immediately before an oops. The kernel documents a setting such as:
ftrace_dump_on_oops trace_buf_size=50KIn this example, the trace buffer size is per CPU, so total allocation grows with CPU count. Choose a size that fits the memory budget and capture needs. Trace persistence is not the same as a full memory dump. See the kernel’s trace debugging documentation.
kdump and kexec
Kdump loads a capture kernel into reserved memory so it can save a crashed kernel’s memory as /proc/vmcore. The broad workflow is: reserve memory; configure and boot the capture kernel; reproduce a crash; save or transfer the vmcore; then analyze it with matching kernel symbols and an appropriate analyzer. The kernel’s kdump guide documents collection and analysis, including examples such as:
cp /proc/vmcore <dump-file>
scp /proc/vmcore remote_username@remote_ip:<dump-file>
makedumpfile -l --message-level 1 -d 31 /proc/vmcore <dump-file>
gdb vmlinux <dump-file>
GDB provides limited analysis for many dump workflows; the crash utility is commonly better suited to Kdump-format dumps. Kdump is not guaranteed: the capture kernel, reserved memory, storage/network path, and reset sequence must all work. Embedded constraints include precious RAM, watchdog timeouts, loss of power, flash wear, dump size, and sensitive memory contents. Test the complete recovery path before relying on it.
Common mistakes and safe cleanup
- Using symbols from a different build: verify image/build ID, kernel and module versions, libraries, and source revision.
- Starting with a breakpoint for a timing bug: collect trace evidence first; a stop can hide the race or trip a watchdog.
- Enabling too much logging: narrow dynamic-debug and trace filters, watch buffer use, and preserve the first failure.
- Assuming a minimal image has tools: verify
gdbserver,strace,perf, tracefs/debugfs, and dump support before a field incident. - Assuming QEMU is the board: emulator results do not validate electrical, power, DMA, timing, or peripheral behavior.
- Leaving diagnostic access exposed: remove temporary services, restrict ports and consoles, and lock or disable production debug interfaces as appropriate.
- Collecting memory without controls: cores, vmcores, and traces may include secrets or personal data.
When finished, stop tracing and restore the prior state; disable dynamic debug rules; detach GDB rather than leaving a process stopped; and stop any target-side gdbserver session. Before changing tracefs settings, record any configuration already in use so cleanup does not disrupt another diagnostic process.
Quick Recap
Field-ready checklist
- Exact image, hardware revision, source revision, and build ID recorded.
- Matching executable, libraries,
vmlinux, modules, and debug symbols archived. - UART or persistent kernel/service logs available and time correlation understood.
- Reset reason, watchdog behavior, boot count, and uptime captured.
- Kernel command line, architecture, ABI, and tool versions recorded.
- Core-dump policy, storage limits, and privacy controls checked.
- tracefs/debugfs and required packages verified on the actual image.
- Recovery image or recovery shell tested.
- Any KGDB/JTAG route tested on the target board, including watchdog and reset behavior.
- Diagnostic data retention, transfer, access, and deletion plan established.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

