Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Declare the footer as UTF-8, pass it with --footer-html, set the input default with --encoding UTF-8, and decode substituted query-string values with decodeURIComponent(). A reliable footer is a complete HTML document saved as UTF-8, served with a compatible HTTP charset when remote, and rendered with fonts that contain every character you use.
The working command and footer file
For a local input and local footer, use:
wkhtmltopdf --encoding UTF-8 --footer-html footer.html input.html output.pdf--encoding UTF-8 defines the default text encoding for the input document. --footer-html tells wkhtmltopdf to load an HTML footer source. The footer itself still needs an explicit charset declaration and must actually be stored as UTF-8 bytes.
Use a complete UTF-8 HTML document
<!doctype html>
<html>
<head>
  <meta charset="utf-8">
  <style>
    body { margin: 0; font: 9pt Arial, sans-serif; }
    .footer { width: 100%; text-align: center; }
  </style>
</head>
<body>
  <div class="footer">
    <span class="mytitle"></span>
    <span> — page <span class="page"></span> of <span class="topage"></span></span>
  </div>
  <script>
    function subst() {
      const params = new URLSearchParams(window.location.search);
      document.querySelector('.mytitle').textContent = params.get('mytitle') || '';
      document.querySelector('.page').textContent = params.get('page') || '';
      document.querySelector('.topage').textContent = params.get('topage') || '';
    }
    window.onload = subst;
  </script>
</body>
</html>
The compatibility declaration recommended by django-wkhtmltopdf is also valid:
Quick wins for a faster PC:
Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Clear out junk files and repair common Windows errorsFree Scan →<meta http-equiv="Content-Type" content="text/html; charset=utf-8">Use either declaration, not a conflicting pair. Keep the footer’s source file, styles, and scripts in UTF-8. A declaration cannot repair a file that was saved in Windows-1252, Latin-1, or another encoding.
#1 Best Overall
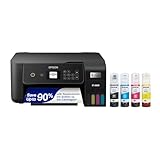
- INNOVATIVE CARTRIDGE-FREE PRINTING — No more dealing with lots of tiny ink cartridges; With this wireless document and photo printer each ink bottle set is equivalent to about 90 individual cartridges²
- LESS FREQUENT INK REPLACEMENT — Replacement ink bottles don't have to be changed nearly as often as ink cartridges¹; When you choose this combination printer, scanner and copier you can print up to 4,500 pages black/7,500 color³
- COLOR PRINTING — Up to 2 years of ink in the box4 (and with every replacement ink set) for fewer out-of-ink frustrations
- ZERO CARTRIDGE WASTE — By using an Epson EcoTank printer you can help reduce the amount of cartridge waste ending up in landfills
- HOME PRINTER DESIGNED FOR RELIABILITY — The Epson EcoTank ET-2800 All-in-One Supertank Color Printer creates vivid, detailed prints and documents thanks to Micro Piezo Heat-Free Technology; Fire off 10 ISO pages per minute1 to easily finish large jobs
How footer substitutions are encoded
wkhtmltopdf exposes footer variables such as [page], [topage], [webpage], [section], and [title]. For custom values, the footer page receives data through its URL query string. Query strings are transport text, so non-ASCII values must be percent-encoded before they are appended and decoded exactly once in the footer script.
Decode with decodeURIComponent()
function subst() {
  const params = new URLSearchParams(window.location.search);
  const title = params.get('mytitle') || '';
  document.querySelector('.mytitle').textContent = title;
}
window.onload = subst;
If your integration provides a raw encoded value rather than using URLSearchParams, decode it explicitly:
const encoded = new URLSearchParams(window.location.search).get('mytitle') || '';
const decoded = decodeURIComponent(encoded);
document.querySelector('.mytitle').textContent = decoded;
Do not use the deprecated unescape(). An issue report found that hard-coded UTF-8 characters rendered correctly while values passed through footer parameters were corrupted; replacing unescape() with decodeURIComponent() addresses that particular substitution path. Do not decode a value twice, because a second pass can turn literal percent sequences into other characters or throw an error.
Encode before building the footer URL
const footerUrl = `file:///absolute/path/footer.html?mytitle=${encodeURIComponent('Résumé — 東京')}`;When invoking wkhtmltopdf from an application, let the URL builder perform the escaping rather than concatenating untrusted text. This preserves spaces, ampersands, question marks, emoji, and non-Latin scripts as one query parameter.
Input encoding, footer encoding, and HTTP encoding are separate
| Layer | What to configure | What it fixes |
|---|---|---|
| Input document | --encoding UTF-8 |
The default interpretation of the main HTML input. |
| Footer document | <meta charset="utf-8"> (or the HTTP-equiv form) |
How the footer HTML is interpreted by the rendering engine. |
| Remote footer response | An HTTP Content-Type with a UTF-8-compatible charset |
How bytes fetched from a server are labeled before parsing. |
| Substitution values | URL-encode on transport; decode once with decodeURIComponent() |
Preserves characters placed in footer query parameters. |
| Glyph rendering | Install a font covering the target script | Displays characters for which the selected font has glyphs. |
These settings are complementary. --encoding UTF-8 is a default for input; it does not repair bytes that were already mis-encoded, a URL that was decoded incorrectly, or a missing font. The libwkhtmltox API likewise expects settings strings as UTF-8 and exposes the equivalent web default-encoding and header/footer HTML URL settings.
Rank #2

- CARTRIDGE-FREE PRINTING — Print lab-quality photos, graphics and creative projects; Get vibrant colors and sharp text with Epson's high-accuracy printhead and Claria ET Premium 6-color inks
- INK BOTTLES — Save on photos1 and creative projects with affordable in-house printing; All-in-one printer allows you to print 4" x 6" photos for about 4 cents each vs. 40 cents with traditional ink cartridges1
- LESS FREQUENT INK REPLACEMENT — Replacement ink bottles don't have to be changed nearly as often as ink cartridges¹; Printer, scanner and copier lets you print up to 6,200 color pages³
- PRINT FOR LONGER — Up to 2 years of ink in the box² (and with every replacement ink set) for fewer out-of-ink frustrations with this wireless printer
- ZERO CARTRIDGE WASTE — Epson EcoTank printer helps reduce the amount of cartridge waste ending up in landfills; Cartridge-free printer uses high-yield ink bottles; Each replacement ink bottle set is equivalent to about 100 individual ink cartridges⁴
Remote footer URLs and application integrations
Serve the footer with an explicit content type
If --footer-html points to HTTPS, configure the response as HTML with a UTF-8 charset, for example Content-Type: text/html; charset=utf-8. Test the exact URL from the same machine and service account that runs wkhtmltopdf. Authentication redirects, a login page, a proxy-generated error, or a response without the expected charset can make a correct local file appear broken.
API settings
For libwkhtmltox, provide UTF-8-encoded strings for the input and footer URLs, set the web default encoding to UTF-8, and use the footer HTML URL setting rather than embedding a text-only footer when markup or non-ASCII characters matter. Keep the same footer file and decoding logic used by the command-line test so that application and shell behavior remain comparable.
Recommended Free Tools
Why --footer-text can fail for non-ASCII text
footer-text is a text-only path and has fewer controls over document charset, markup, and script decoding. An issue report describes non-ASCII footer text being dropped in some production environments and reports footer-html with an explicit charset as a workaround. For accented names, CJK text, emoji, or mixed scripts, use an HTML footer and control the charset, URL transport, and fonts independently.
A repeatable diagnostic procedure
- Make the smallest case. Create a one-page input, a footer containing one known non-ASCII string such as
Résumé — 中文 — 日本語, and no external CSS or JavaScript except the substitution code. - Verify the bytes. Open the footer in an editor that reports encoding and resave it explicitly as UTF-8. Do not rely on the filename or editor default.
- Declare the charset. Put
<meta charset="utf-8">in the footer’s<head>. - Run the explicit command. Include
--encoding UTF-8and--footer-htmlin the same command used for the test environment. - Test substitution separately. First hard-code the text. Then pass it as a query value encoded with
encodeURIComponent()and decode it once in the footer. This distinguishes parsing errors from transport errors. - Check fonts. Install a font with glyph coverage for every target script and make sure the wkhtmltopdf process can access it.
- Match production. Repeat the test with the production wkhtmltopdf build, operating system, locale, user account, environment variables, and network path.
- Record the version and case. Keep the exact command, version information, input, footer, and output when reporting a failure. A minimal reproducible HTML/CSS/JavaScript example is more useful than a full application export.
Troubleshooting by symptom
Hard-coded text is correct, but a substituted title is garbled
The footer document is being parsed as UTF-8, so inspect the query-string path. Percent-encode the value before transport and replace unescape() with one decodeURIComponent() call. Ensure an intermediate framework has not decoded and re-encoded the parameter first.
The body is correct, but the footer is not
The body and footer are separate documents. Add the footer’s own charset declaration, verify its bytes, and use --footer-html. The input option alone does not set the footer document’s bytes or response headers.
Rank #3
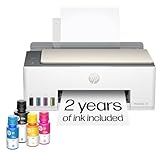
- SET IT UP ONCE AND PRINT WITH CONFIDENCE. No complicated maintenance. Just easy, reliable printing you can count on.
- INK FOR YEARS. NOT MONTHS. Up to 2 years of ink included. Get thousands of pages of cartridge-free printing. More pages, less hassle
- KEEPS PRINTING WELL AFTER COMPETITORS HAVE QUIT. No complex maintenance. Sharper text, richer colors.[2] Only with HP Smart Tank
- PREMIUM SUPPORT - Strong technical expertise to solve issues faster
- THE LAST PRINTER YOU'LL EVER NEED. Enjoy years of refillable, cartridge-free printing.
Every non-ASCII character disappears
Check whether the environment is dropping characters on the text-only footer path. Switch to HTML, confirm the footer response is actually the intended file, and inspect installed fonts. Missing glyphs can look like an encoding problem even when the bytes are valid.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Chinese, Japanese, or another script shows boxes
Install a font that covers that script and make it available to the account running wkhtmltopdf. Test outside your interactive desktop session: services often have a different font directory, locale, or home directory.
A remote footer works locally but fails in production
Compare the HTTP response, redirects, TLS/proxy behavior, authentication, and Content-Type charset. Then compare the wkhtmltopdf build and service account. A remote URL that returns an error page is not the same input as the local UTF-8 footer.
decodeURIComponent() throws an exception
The value is not valid percent-encoded UTF-8, or it has already been decoded and contains a stray percent sequence. Log the raw query value, encode at the producer, and decode exactly once at the consumer.
Reliability and operational considerations
- Pin the renderer. Keep the same wkhtmltopdf version in development and production; rendering behavior can vary between builds.
- Use deterministic assets. Local footer files and installed fonts remove network, redirect, and authentication variables. If you must fetch remotely, monitor the response headers and availability.
- Keep footer scripts small. Read only the parameters you need, use
textContentrather than injecting HTML, and avoid asynchronous work that may not finish before rendering. - Protect URL values. Encode user-controlled text and avoid putting secrets in query strings, which may be logged by proxies or process diagnostics.
- Validate the PDF. Inspect several pages, including the first and last, and verify page counters, accented text, CJK glyphs, and line wrapping.
Or skip the browser setup
If your actual goal is a clean image or PDF of a web page rather than a locally rendered wkhtmltopdf document, ScreenshotNeo provides a one-request screenshot API. It accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; bot checks, blank pages, failed loads, timeouts, and cache hits are not billed. Each response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server gives AI agents tools named take_screenshot, get_page_info, and capture_pdf.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Clear out junk files and repair common Windows errors3Fix the driver behind crashes, sound loss and screen glitchesFor the API details and all options, see the ScreenshotNeo documentation. A cURL request is:
Rank #4
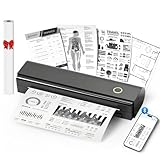
- Wireless Bluetooth Printer: Portable thermal printer compatible with iPhone, Android phones, iPad and tablet computers via Bluetooth. For smartphones, please download the "Nada Print" App. You can also connect to laptops and computers for printing using a USB-C cable. (Note: Laptops and computers can only be connected via USB and require the installation of a driver first. Bluetooth connection is not supported.)
- No-ink printing: Only supports US Letter and A4 size thermal paper.(Doesn't support regular paper) The no-ink portable thermal printer uses direct thermal technology, requiring no ink, toner or ribbons, making it environmentally friendly, cost-effective and time-saving. The thermal printer package comes with a roll of US Letter thermal printing paper. Note: When installing the paper, remember to switch the paper size switch on APP
- Clear Print: NDYIN N80 portable thermal printer adopts high-definition printing technology, with a 203DPI resolution to provide you with clear printing results. This mobile printer is compatible with roll paper, folded paper and tattoo transfer paper, supporting printing from your mobile phone PDF, Word, pictures and web pages anytime and anywhere. It is recommended to use our NDYIN thermal paper to achieve good printing quality
- Portable wireless printer for travel: The thermal printer is equipped with a built-in 1500mAh rechargeable battery, which can print 160 sheets of 8.5" x 11" thermal paper after being fully charged. It weighs only 1.5 pounds and is compact in size. This ink-free portable printer can be easily carried in a backpack or briefcase! It is perfect for business travel, cars, small offices, construction sites, schools and homes. You can print documents, contracts, invoices and boarding passes anytime and anywhere
- The N80 thermal printer has a wide range of uses. The package includes the N80 printer, a roll of US Letter paper(7m/roll), a user manual, a guide card, a type-C soft cable and a type C adapter. Note: The charging adapter is not included. Special thermal paper is required for use; ordinary paper cannot be used. This ink-free portable thermal printer is suitable for various scenarios such as home, school, travel, office, and outdoor, meeting the printing needs of different groups of people. This tattoo template printer is also compatible with tattoo transfer paper, making it an ideal choice for tattoo art
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpThe same request in Python:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
And in Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
ScreenshotNeo includes full-page captures with lazy images loaded, element selection, dark mode, device and viewport controls, retina scale, PDF paper and page-range settings, custom CSS and JavaScript, click and wait actions, request blocking, headers, cookies, user-agent, authorization, timezone, geolocation, transparent backgrounds, resizing, selectable caching TTLs, signed image links, asynchronous jobs with signed webhooks, bulk capture for 100 URLs per call, a usage API, and an OpenAPI specification. Every feature is on every plan: 1,000 screenshots per month are free with no card; paid plans start at $5 for 3,000, and annual billing provides two months free. Create a free ScreenshotNeo account.
Frequently Asked Questions
Does the HTML5 charset tag replace --encoding UTF-8?
No. The meta tag declares the footer document’s encoding, while --encoding UTF-8 sets the default encoding for the input document. Configure both when both documents are UTF-8.
Can a correct charset declaration fix missing Chinese glyphs?
No. Charset controls byte interpretation; a font with the required glyphs is still needed. Install and expose an appropriate font to the wkhtmltopdf process.
Is footer-html required for page-number variables?
Use the HTML footer path when you need markup, scripts, custom decoding, or reliable non-ASCII handling. The footer HTML can read variables such as [page] and [topage] through the query string.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

