An AI proxy—also called an LLM gateway—is the intermediary between your application and one or more model providers. Instead of embedding separate provider endpoints, keys, quotas and response formats in every client, your software sends one request to the gateway. The gateway authenticates it, enforces policy, chooses an eligible deployment, translates the request, calls the provider, and returns a client-facing response.
The sequence below follows the flow documented for the LiteLLM gateway. Treat it as a concrete implementation example, not a universal standard: other gateways may perform checks in a different order, expose different controls, or log at a different time.
What an AI proxy does
A proxy presents a stable endpoint to your application while hiding provider-specific details behind it. A single OpenAI-style interface can be mapped to different upstream APIs, but a common interface does not make providers identical. Supported parameters, streaming behavior, tool calling, error formats and model capabilities still depend on the selected provider and the gateway configuration.
LiteLLM describes its unified interface as supporting “100+ LLMs”; that is a vendor-reported coverage figure and can change as integrations are added or removed.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
#1 Best Overall
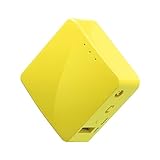
- 【WIRELESS MOBILE MINI TRAVEL ROUTER】 Convert a public network (wired or wireless) to a private Wi-Fi for secure surfing. Tethering. Powered by any laptop USB, power banks or 5V/2A DC adapters (sold separately). 39g (1.41 Oz) only, portable and pocket friendly. 2.4GHz ONLY
- 【OPEN SOURCE & PROGRAMMABLE】 OpenWrt pre-installed, USB disk extendable.
- 【LARGER STORAGE & EXTENDABILITY】 128MB RAM, 16MB Flash ROM, dual Ethernet ports, UART and GPIOs available for hardware DIY.
- 【OPENVPN CLIENT】 OpenVPN client pre-installed, compatible with 30+ VPN service providers.
- 【PACKAGE CONTENTS】 GL-MT300N-V2 (Mango) mini router (2-year Warranty), USB cable, Ethernet cable, User Manual. Please update to the latest firmware.
The request lifecycle, step by step
1. The client sends a request to the gateway
Your application, SDK, command-line tool or internal service targets the proxy URL rather than a provider URL. It sends the model identifier, messages or prompt, generation settings and credentials expected by the gateway.
At this point the gateway can become the consistent control point for applications written in different languages. The client does not need to know which provider will ultimately serve the request.
2. Authentication and access checks run
In LiteLLM’s documented flow, the gateway checks a virtual key. It looks in cache first and consults the database when the key is not cached. The gateway also checks whether that key is still within its configured budget.
A failed or expired key should stop before an upstream model call. This prevents unauthorized requests from consuming provider quota. Exact key formats, scopes and budget semantics vary by implementation.
3. Rate limits are evaluated
The documented LiteLLM checks can apply limits at several scopes:
- the gateway server;
- the virtual key;
- the user; and
- the team.
Those limits may be measured in requests per minute or tokens per minute. Do not assume every gateway has these four scopes or uses those units. A production design should document what happens when a limit is exceeded, including the returned status, retry guidance and whether streaming requests count differently.
4. The router selects a deployment
Once a request is authorized and within policy, a router chooses an eligible deployment. A deployment is a configured combination of a model, provider endpoint and credentials. The router may balance traffic across several deployments in the same model group.
Selection is not arbitrary. Weighting, health state, capacity, configured priorities, session affinity and model-group rules can all affect the result. If conversational continuity matters, verify whether the gateway pins a session to one deployment or can move later requests elsewhere.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Rank #2

- 【Advanced Home Data & Media Hub】For advanced home users who need phone backup, file storage, and centralized data management. Centralize family photos, 4K videos, movies, computer backups, and personal files in one place while running multiple apps for home entertainment and everyday data management. Suitable for households with growing digital libraries and multiple NAS use cases.
- 【Built for Creators, Media Servers & Advanced Apps】Powered by the Intel N100 Quad-Core CPU, 8GB DDR5 RAM, 2.5GbE networking, and dual M.2 NVMe slots, DXP2800 handles large files and heavier workloads with ease. Run Docker, virtual machines, and media server applications compatible with Plex—ideal for content creators, tech enthusiasts, and advanced home users managing 4K videos, RAW photos, personal media libraries, and multiple NAS apps.
- 【Up to 80TB for Growing Digital Libraries】 Supports up to 80TB of storage using two HDD bays and two M.2 NVMe SSD slots for family photos, movies, RAW photos, 4K videos, work files, and device backups. AI photo management supports recognition of people, objects, scenes, and locations, album organization, and duplicate photo detection. HDDs and SSDs are not included.
- 【AI-powered Home Surveillance】Turn DXP2800 into a centralized home surveillance hub by connecting compatible network cameras and storing recordings locally on your NAS. AI-powered features include Face Recognition, People Detection, and Pet Detection, helping advanced home users review important events more efficiently while managing home surveillance and personal data in one place.
- 【One data Center Across Your Devices】Keep files from desktops, laptops, phones, tablets, and other devices together instead of scattered across cloud accounts and external drives. Access, back up, organize, and share data across Windows, macOS, Android, iOS, web browsers, and compatible smart TVs—ideal for creators and advanced home users working across multiple devices.
5. The proxy translates and forwards the request
The documented proxy accepts a unified OpenAI-style request and maps it to the selected provider’s API and parameter names. It then makes the upstream HTTP call.
Translation removes repetitive client integrations, but it is not a promise of feature parity. A parameter accepted by one provider may be ignored, transformed or rejected by another. Check the gateway’s compatibility notes for structured output, tool calls, vision, embeddings, streaming and provider-specific settings.
6. The provider processes the request
The selected provider performs authentication on its side, queues or schedules the work, runs the model and returns a result or an error. The gateway receives that upstream response and converts it into the format exposed to your client.
Latency now includes gateway processing, network travel to the provider, provider queue time, model generation and the return path. A proxy can simplify operations without making the model itself faster.
7. Retries and fallbacks may handle failures
In the LiteLLM router description, a retry attempts another deployment in the same model group. A fallback moves to another configured model group. These are different decisions:
- Retry: try another deployment that is intended to provide the same model group.
- Fallback: switch to a different configured model group, potentially with different capabilities, quality or price.
Retry behavior is policy-driven, not guaranteed. The gateway may retry only selected error types, and a retry can duplicate work if the upstream request was accepted but the response was lost. Configure idempotency where the provider supports it, cap attempts, and record which deployment ultimately answered.
8. Usage and logs are recorded
LiteLLM’s lifecycle documentation says spend logging, rate-limit accounting and logging callbacks run asynchronously after the response returns. That can reduce response-path overhead, but it also means a client may receive a result before usage data is visible in a dashboard.
Other gateways may log synchronously, asynchronously or not at all. Confirm retention, destinations, redaction and failure behavior before sending sensitive prompts. Decide whether prompts, completions, token counts, model names, latency and provider errors are allowed in your operational records.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Repair Windows errors before they cause bigger problemsFix Now →Rank #3

- One Place for All Your Data - Consolidate scattered files from multiple computers, phones and external drives into one accessible hub with 100% ownership
- Professional File Collaboration - Share projects with clients, sync documents across teams and maintain version control without Dropbox fees
- Automated Backup Protection - Set-and-forget backups for Macs, PCs and mobile devices to multiple destinations including cloud and external drives
- DIY Surveillance System - Transform IP cameras into a professional monitoring solution with motion alerts, recording schedules and remote viewing
- 2-Year Warranty - Reliable hardware backed by Synology's expert customer support team and ongoing software updates
What the proxy changes—and what it does not
One endpoint, several providers
Applications can use one internal endpoint while operators add or remove provider deployments behind it. This reduces the number of client-side integrations and centralizes credential handling.
Central policy enforcement
Authentication, budgets, quotas and concurrency rules can be applied before expensive upstream work. Policies still need careful scope design: a team-wide token limit behaves differently from a per-user request limit.
Translation with boundaries
Adapters make common requests portable, but model context limits, safety behavior, tool semantics and output guarantees remain provider-specific. Test every capability your application depends on rather than assuming a successful basic chat request proves compatibility.
Operational visibility
A gateway can attach request IDs, collect spend data and expose deployment-level metrics. Determine whether those records are complete when retries occur and whether asynchronous callbacks can be delayed or lost.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchHow routing decisions affect an application
Routing is the point where an abstract model name becomes a concrete upstream destination. Before adopting a policy, answer these questions:
- Which deployments are eligible for this model group?
- Does the router balance evenly, use weights or prefer a primary?
- How is an unhealthy deployment removed and restored?
- Is session affinity required for multi-turn conversations?
- What happens when every deployment is over quota?
- Can a fallback change model quality, context length, region or data-processing terms?
Keep model-group definitions version-controlled. A configuration change can alter latency, output behavior and cost without any client code changing.
Security and privacy checkpoints
Protect both layers of credentials
Clients should normally hold a gateway credential, while provider keys remain server-side. Restrict virtual keys by user, team, model or budget where supported, rotate them, and avoid placing provider secrets in browser code.
Control sensitive logging
Prompts and completions can contain personal, confidential or regulated data. Set retention and redaction rules before enabling callbacks. Verify where logs are stored and who can query them.
Recommended Free Tools
Rank #4
- Unlimited bandwidth, unlimited data.
- Super-fast VPN and one tap connect.
- Free worldwide multiple servers.
- Works with all type of data carries. (Wi-Fi, 4G, LTE, 3G).
- No registration, sign up needed.
Make policy failures explicit
Return distinguishable errors for invalid credentials, exhausted budgets, rate limits, unavailable deployments and provider failures. A generic 500 response makes clients retry the wrong condition and obscures incidents.
Performance, reliability and cost considerations
A proxy adds at least one network hop and its own processing. Keep it near your applications and providers where practical, reuse connections, and measure time to first token separately from total completion time. Streaming can improve perceived responsiveness but does not remove provider or network latency.
Retries can improve availability while increasing token use and latency. Fallbacks can keep a service operating but may change price or answer quality. Budget accounting should include attempted calls according to the gateway’s documented semantics, especially when an upstream response is lost.
There is no universal performance or cost improvement attributable to using a proxy. The result depends on routing policy, provider prices, cache behavior, retry rules and traffic shape. Measure these separately: gateway overhead, provider latency, tokens, retry rate, fallback rate and rejected requests.
Free tools Windows power users keep installed
One-click scans. No signup required.
Choosing an AI gateway: questions to verify
No product ranking is established by the available documentation. Use this checklist when comparing implementations:
- Coverage: Which providers, endpoints and capabilities are supported, and how faithfully are parameters translated?
- Routing: Are load balancing, health checks, priorities, session affinity, retries and fallbacks configurable?
- Controls: What key scopes, budgets, rate limits and concurrency limits exist?
- Observability: Where do logs go, how long are they retained, what is redacted, and is accounting synchronous?
- Deployment: Can you self-host, or is it managed? How are versions, secrets and configuration promoted?
Troubleshooting common lifecycle failures
401 or invalid-key responses
Check that the client is sending the gateway key in the expected header or parameter, that the key belongs to the correct environment, and that it has not expired or exceeded its budget. Do not substitute a provider key unless the gateway explicitly requires one.
429 responses
Identify whether the server, virtual key, user or team limit was reached. Honor the gateway’s retry guidance, use exponential backoff with a cap, and reduce concurrency or token volume. Blindly retrying can extend the outage.
Model or deployment unavailable
Confirm that the requested model group has an enabled deployment, valid provider credentials and remaining quota. If a fallback is configured, inspect whether it changed model behavior or price.
Best Value

- Complete Phone & Computer Backup - Automatically protect photos, documents and videos from iPhone android, Mac and Windows to one secure location
- Your Private File Cloud - Access files from anywhere and share large projects with family or clients without relying on expensive cloud subscriptions
- Smart Home Security Hub - Monitor your home 24/7 with AI-powered surveillance that detects people, vehicles and sends instant alerts
- 100% Data Ownership - Keep full control of your personal data with multi-platform access and no monthly subscription fees
- 2-Year Warranty - Reliable hardware backed by Synology's expert customer support team and ongoing software updates
Parameter or feature errors
Compare the request with the selected provider’s supported features. Remove provider-only fields, use the gateway’s documented equivalent, or route capability-specific traffic to a deployment that supports it.
Unexpected duplicate charges or work
Inspect retry logs and request IDs. A timeout does not prove the provider rejected the request; it may have completed before the connection failed. Use idempotency controls where available and keep retry policies narrow.
Missing or delayed usage data
If accounting is asynchronous, the response can arrive before spend logs or callbacks. Check callback queues and error logs, and do not treat an immediately empty dashboard as proof that the request was free.
A concrete API-gateway example: ScreenshotNeo
For a different automation use case, ScreenshotNeo provides a website screenshot API and MCP server. Its one-call model illustrates the same broad gateway idea: a client sends a request to one endpoint, the service applies capture controls, and the result is returned.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsScreenshotNeo removes cookie or consent banners, newsletter popups and chat widgets before capture. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads and cache hits are not billed; response headers identify the page verdict and billing result. Its MCP server exposes take_screenshot, get_page_info and capture_pdf for Claude, Cursor and other MCP clients.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
See the ScreenshotNeo documentation for request options. It supports full-page captures with lazy images loaded, CSS-selector element capture, dark mode, 12 device presets and custom viewports, retina scale, PDF paper sizes and page ranges, HTML/CSS rendering, custom JavaScript and CSS, clicks, waits, ad or tracker blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, configurable-TTL caching, signed links, asynchronous webhooks, bulk capture of up to 100 URLs per call, a usage API and an OpenAPI specification.
Plans include 1,000 shots per month free with no card; paid plans start at $5 for 3,000 shots. Every feature is on every plan, and yearly billing gives two months free. Create a free ScreenshotNeo account to try it.
FAQ
Frequently Asked Questions
Is an AI proxy the same as a load balancer?
It can include load-balancing behavior, but it also commonly handles authentication, provider translation, budgets, model routing, retries and usage accounting.
Does a proxy make every model API compatible?
No. A unified request format hides many differences, but provider capabilities, limits and error behavior still need verification.
Should retries always be enabled?
No. Configure them for specific transient failures, cap attempts, and account for the possibility that an upstream request completed before a timeout.
Can a gateway see my prompts?
Potentially. Visibility depends on its logging and callback configuration, so review retention, redaction, access and data-processing controls before sending sensitive content.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

