Recommended Free Tools
Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Synthetic data is not a magic replacement for real speech, and public evidence does not show that it is the sole reason for Deepgram’s speech-recognition performance. Deepgram describes synthetic code-switched speech, targeted augmentation, audio-embedding analysis, curated real-world datasets, and domain-specific data as parts of a broader model-development process.
The important idea is the feedback loop: identify where transcription fails, generate controlled examples for those weak spots, combine them with real recordings, and verify the result on held-out production-like audio.
What synthetic data means in speech recognition
In automatic speech recognition (ASR), synthetic data usually means an artificially created audio–transcript pair. An engineering team starts with known text, generates or modifies audio, and uses the resulting pair to train or adapt a model.
That umbrella includes several different techniques:
#1 Best Overall

- 360 Degree Position Adjustable Gooseneck Design --Plug and play USB microphone Pick up the sound from 360-degree with high sensitivity, in the best possible location for sound to your PC gaming, dragon voice dictation, and talk to Cortana
- Mute Button & LED Indicator --One-click to mute/unmute your microphone for pc, Build-in LED indicator tells you the working status at any time
- Intelligent Noise-Canceling Tech --Premium omnidirectional condenser microphone with noise-canceling technology can pick up your clear voice and reduce background noise and echo
- USB Plug&Play(1.8/6ft USB Cable) -- No driver required. Just need to plug & play for the microphone to start recording, well compatible with Windows(7, 8, 10 and 11) and macOS. (NOT compatible with Xbox/Raspberry Pi/Android)
- Solid Construction--Adopting premium metal pipe and heavy-duty ABS stand to make sure that you will be satisfied with our computer mic quality
- Synthetic speech: text converted into speech by a text-to-speech system.
- Audio augmentation: real speech modified with noise, reverberation, compression, clipping, bandwidth limits, or simulated microphone distance.
- Synthetic text: deliberately constructed sentences containing rare names, product terms, medical vocabulary, numbers, acronyms, or commands.
- Synthetic conversations: simulated dialogue with turn-taking, interruptions, or agent interactions.
- Synthetic multilingual data: generated utterances that contain language changes or other multilingual patterns.
These methods solve different problems. TTS can provide many labeled voices, augmentation can approximate difficult acoustic conditions, and targeted text generation can increase exposure to words that rarely occur in ordinary training data.
Why real speech alone leaves gaps
Real recordings remain essential because they contain natural hesitations, disfluencies, interruptions, crosstalk, spontaneous phrasing, device artifacts, and unpredictable environments. But real data is not automatically balanced or sufficient.
A large collection may still contain too few examples of:
- Minority accents and dialects.
- Rare languages and code-switching.
- Medical, legal, financial, or technical terminology.
- Poor microphones, telephony channels, reverberant rooms, or distant speakers.
- Names, addresses, serial numbers, currency, and other alphanumeric phrases.
Medical transcription illustrates the problem. It requires specialized vocabulary, multiple specialties, varied accents, accurate human labels, and strict privacy controls. Deepgram describes these challenges in its overview of medical transcription. In sensitive domains, collecting and sharing enough authentic recordings can be expensive, slow, or impossible.
There is also a distribution problem: more recordings of the same speakers, devices, and environments may add volume without adding useful coverage. Synthetic generation allows a team to deliberately target a measurable weakness instead of hoping that another random sample fixes it.
How synthetic data fills a known weakness
Suppose a contact-center model repeatedly misrecognizes a product name. The team can place that term into realistic sentences, generate multiple pronunciations and speaking rates, and apply telephony compression and background noise. A medical system could do something similar with drug names, specialties, or dosage instructions.
Other controllable variables include:
- Voice characteristics and speaking rate.
- Pronunciation variants and prosody.
- Noise, room acoustics, microphone distance, and bandwidth.
- Sentence context rather than isolated dictionary words.
- Language transitions in multilingual conversations.
- Commands, identifiers, addresses, and other structured phrases.
The benefit is not simply producing a large number of files. It is producing examples aimed at a known region of the model’s error distribution.
Why known transcripts help—and why they are not automatically correct
ASR training depends on correctly paired audio and text. Synthetic generation starts with a controlled transcript, so the intended label is known before the audio is produced. That is valuable for rare terminology, proper names, acronyms, numbers, and code-switched sentences.
However, the source text does not prove that the generated recording said every word correctly. A TTS system may mispronounce a name, expand an abbreviation unexpectedly, omit a word, or produce unnaturally clean speech. Synthetic labels therefore still need quality control, audio–text alignment, pronunciation checks, and human review of important examples.
Rank #2

- 【HIGH DEFINITION AUDIO 】 This microphone embeds a patented audio filter in order to record only your voice. Good for home studio, Chatting, Skype,Discord, Yahoo Recording, YouTube Recording, Google Voice Search and Steam.
- 【PLUG & PLAY 】 You just need to plug the microphone and it will work ! No software to install. A single button to turn it on or off. Compatible with every operating system - Mac OS X Windows Linux - and every PC brand.
- 【SMOOTH AND CLEAR】 Noise cancellation and isolates the main sound source, This USB Microphone is perfect for videoconferencing, Skype, dictation or voice recognition. The audio filter will give you a clear and confident voice. Anti-pop filter included !
- 【MUTE BUTTON & LED INDICATOR 】One click to mute/unmute your microphone,Build-in LED indicator tells you the working status at any time.Built with a mix of metal and heavy duty plastic, it's solid as a tank. It is very stable thanks to its weight.360 Degree Position Adjustable Gooseneck Design --Adopting the design of metal gooseneck pipe pickup the sound from 360-degree with high sensitivity
- 【SATISFACTORY SERIVCE】- 30 days unconditional return. TKGOU Customer service 2 years, We are committed to ensuring that you are 100% satisfied, If you have any questions, please contact us directly.We will provide you with a more friendly and satisfactory service.
What Deepgram publicly says about Nova-3
The strongest public evidence comes from Deepgram’s Nova-3 announcement. Deepgram describes a multi-stage training approach that combines synthetic code-switched data at large scale with curated real-world datasets. It also describes several related data and modeling techniques.
Audio embeddings and acoustic coverage
Deepgram says an audio-embedding framework projects recordings into a compressed latent space. This helps identify and sample underrepresented acoustic conditions in the training data.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
The significance is broader than the particular implementation: synthetic data is most useful when guided by observed gaps. Instead of generating random speech, an organization can look for missing combinations of noise, device, distance, speaking style, or channel quality and create targeted coverage.
Long-tail vocabulary augmentation
Deepgram also describes targeted augmentation for specialized, long-tail vocabulary. The aim is to place rare words into realistic acoustic and linguistic contexts rather than treating them as isolated dictionary entries.
This distinction matters. A model that has seen a rare term only in clean, carefully pronounced audio may still fail when the term appears in a hurried phone call or a noisy meeting.
Code-switching
Deepgram says Nova-3 was trained with synthetic code-switched data alongside curated real-world data and lists real-time code-switching support across English, Spanish, French, German, Hindi, Russian, Portuguese, Japanese, Italian, and Dutch.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Language detection means identifying the language being spoken. Code-switching recognition means transcribing a natural transition between languages within the same conversation. The latter is harder because the model must handle changing vocabulary, pronunciation, grammar, and acoustic context without treating the switch as an error.
Deepgram’s code-switching guide recommends building evaluation sets from actual production audio. That qualification is important: synthetic examples can increase training coverage, but real conversations are still needed to determine whether the improvement transfers.
Difficult audio–text examples
Deepgram says its audio-text alignment techniques allow it to train on difficult or “adversarial” examples that traditional approaches might discard. Here, “adversarial” should not automatically be read as a formal security attack. In this context, it can refer to deliberately challenging audio–text cases that test the limits of the model.
Rank #3

- [Convenient Setup] Plug and play recording USB microphone for PC, with 5.9-Foot USB cable included for computer PC laptop, is connected directly to USB-A port for recording music, computer singing or podcast. The office condenser microphone for computer is easy to use and install. (NOT compatible with Xbox and Phones)
- [Durable Metal Design] Solid sturdy metal construction design, the computer microphone for Zoom meetings with stable tripod stand is convenient when you are doing voice overs or livestreams on YouTube. Durable material extends the service life of the voice-over microphone.
- [Mic Volume Knob] Gaming condenser USB mic compatible for PS4 with additional volume knob itself has a louder or quieter adjustment and is more sensitive. Your voice would be heard well enough through the zoom microphone USB when gaming, skyping or voice recording. Also, you can adjust your volume to zero and protect your privacy.
- [Widely Use] USB-powered design, the condenser microphone for recording no need the 48v Phantom power supply, works well with Cortana, Discord, voice chat and voice recognition. The podcast microphone for Mac, with USB-B to USB-A/C cable, is compatible with desktop, laptop or PS4/PS5, which meets most of your daily recording needs.
- [Clear Output Voice] Cardioid condenser microphone for PC captures your voice properly, producing clear smooth and crisp sound. Great computer recording mic for gamers/streamers/youtubers focus on the main source and reduces background noise. The streaming microphone does the job well for broadcast ,OBS and teamspeak.
The real advantage is the data-engineering loop
The most defensible interpretation of Deepgram’s approach is not “generate as much synthetic speech as possible.” It is a closed-loop process:
Free tools Windows power users keep installed
One-click scans. No signup required.
- Measure errors: evaluate transcription by vocabulary, language, accent, noise, device, and use case—not only one overall word-error rate.
- Locate gaps: determine whether failures involve a rare term, code-switch, acoustic condition, alignment issue, or natural conversational behavior.
- Generate targeted examples: create synthetic speech, text, or acoustic variations specifically for the missing coverage.
- Mix synthetic and real data: control sampling and retain enough authentic speech to preserve natural behavior.
- Retrain or adapt: update the model or a domain-specific version.
- Test on held-out real audio: check whether the improvement appears outside the generated dataset.
- Check regressions: verify that specialist improvements have not damaged general vocabulary, other languages, or other speaker groups.
Deepgram has also described synthetic data generation alongside data curation, model adaptation, model hot-swapping, and customer-relevant evaluation in its broader enterprise platform material. That does not disclose the company’s complete proprietary training recipe, but it supports the view that synthetic data is one component of a larger system.
Why code-switching is a useful test case
Code-switching exposes both the value and the limits of synthetic data. It is possible to construct sentences that switch between languages and generate many controlled examples. That can help a model see transitions that are rare in a conventional dataset.
But real code-switching varies in ways that are difficult to script: speakers may switch languages mid-phrase, retain an accent from one language while speaking another, interrupt one another, use slang, or switch because of a particular topic. A synthetic dataset can cover selected patterns without representing the full sociolinguistic range.
For that reason, a serious evaluation should include authentic production recordings, with appropriate privacy controls and human transcription. Synthetic performance alone is not evidence that a model will handle real multilingual conversations.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsWhat can go wrong?
Distribution mismatch
Synthetic recordings may be cleaner, more evenly paced, and more intelligible than real speech. A model can improve on synthetic tests while becoming no better in a noisy contact center or reverberant meeting.
Mitigation: evaluate on held-out real audio segmented by device, noise, accent, language, and application.
Generator overfitting
If most generated examples come from one TTS engine or a small set of voices, the ASR model may learn generator-specific artifacts rather than general speech patterns.
Mitigation: vary voices and generation conditions where appropriate, use multiple sources when rights permit, and retain substantial real speech in training and evaluation.
Rank #4

- Microphone grille with optimized structure
- Integrated pop filter
- International products have separate terms, are sold from abroad and may differ from local products, including fit, age ratings, and language of product, labeling or instructions.
Accent caricature
Synthetic accent controls do not automatically reproduce authentic dialect or speaker diversity. An artificial accent may simplify real pronunciation variation or encode stereotypes.
Mitigation: treat generated accents as augmentation, not demographic representation, and validate results with recordings from real speakers.
Transcript and pronunciation errors
A generated file can carry the wrong label if the TTS system mispronounces, omits, or changes part of the requested text.
Mitigation: use forced alignment, pronunciation checks, audio inspection, and human sampling for high-value vocabulary.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minutePC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Synthetic-data collapse
If synthetic material overwhelms authentic speech, the model may become tuned to artificial timing, pronunciation, and acoustics.
Mitigation: control mixture weights, run real-data regression tests, and compare multiple training recipes.
Benchmark contamination
Generated prompts can accidentally overlap with evaluation text or public benchmark material.
Mitigation: separate generation and evaluation sets, deduplicate text and audio, and version the datasets.
Specialization regressions
Domain adaptation can improve medical, legal, or product vocabulary while reducing general-domain performance. Deepgram’s large-vocabulary guidance discusses this type of customization trade-off.
Best Value
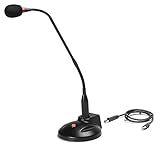
- The GN-USB-2 gooseneck is specially designed for professional voice communications. The GN-USB-2 is compatible for applications such as Hands-free dictation, PC recording software, voice recognition and internet chat.
- Features: Plug n Play, Noise cancelling, On/Off LED indicator, Detachable USB A~B cable, 16 inch adjustable neck, Weight base with non-skid rubber mounts
- Specifications: Element: fixed-charge back plate, permanently polarized condenser, Polar Pattern: Hypercardioid, Sensitivity: -40 +/- 2dB(0dB=1V/Pa at 1KHz), Frequency Response: 40Hz~16KHz, Output Impedance: 75-Ohm +/- 30% Max Input S.P.L.: 138dB, Signal/Noise Ratio: 65dB, Output Connector: USB A~B. Power Supply: Phantom Power 3V DC
- Operating Systems: Microsoft Windows 2000, Windows XP, Windows 7 and Windows 8 , Apple Mac Os9 and all OX X variations
Mitigation: use replay data, mixed-domain testing, and separate specialist and general performance reports.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.How to evaluate a synthetic-data claim
Whether a synthetic-data pipeline is useful should be judged with more than a single headline accuracy number.
| Dimension | What to measure |
|---|---|
| Accuracy | Word error rate, character error rate, entity accuracy, and keyword recall. |
| Robustness | Noise, reverberation, clipping, bandwidth, and microphone distance. |
| Coverage | Accents, dialects, languages, code-switching, and speaker diversity. |
| Vocabulary | Names, medical terms, products, numbers, and acronyms. |
| Naturalness | Disfluencies, timing, interruptions, crosstalk, and spontaneous speech. |
| Transfer | Performance on held-out real recordings. |
| Fairness | Error rates across speaker, language, and accent slices. |
| Label quality | Alignment, pronunciation, formatting, and normalization. |
| Regression risk | General-domain performance after specialization. |
| Provenance | Source text, voice rights, generator version, transformations, and dataset history. |
The most informative experiment is an ablation study comparing:
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →- Real data only.
- Synthetic data only, mainly as a diagnostic.
- Real data plus synthetic data.
- Separate synthetic categories, such as vocabulary, noise, and code-switching.
- Different synthetic-to-real mixture weights.
- Different generators or augmentation recipes.
Without these comparisons, it is difficult to say how much improvement came from synthetic data rather than better curation, architecture, labeling, or ordinary real-data growth.
What is publicly known—and what is not
Deepgram publicly discusses synthetic data generation and describes synthetic code-switched data, acoustic-condition sampling, long-tail vocabulary augmentation, and curated real-world data for Nova-3. However, the available public material does not establish:
- The exact synthetic-to-real data ratio.
- The specific TTS providers or internal generators used for Nova-3.
- The dataset size for each synthetic category.
- The sampling schedule or mixture weights.
- Accuracy improvements attributable only to synthetic data.
- The complete training recipe or reproducible ablation results.
It would therefore be inaccurate to say that Deepgram primarily trains on synthetic speech or that synthetic generation alone explains Nova-3’s performance.
Deepgram has separately published a wake-word experiment using TTS voices, real recordings, negative mining, and augmentation. The company reports that 1,000 base TTS samples became more than 400,000 augmented examples and describes an experiment-specific TTS cost of roughly $0.10. Those figures demonstrate the scalability of one wake-word pipeline; they are not evidence of the complete Nova ASR recipe and should not be generalized to speech-to-text training.
What customers can actually use
There are three different choices that are often confused:
- Hosted transcription: use Deepgram’s speech-to-text API for production recognition.
- Enterprise customization: work with Deepgram on domain vocabulary, model adaptation, or related services. Its large-vocabulary material describes enterprise custom training and a Model Improvement Partnership Program; availability and operational details depend on the agreement.
- Build an internal pipeline: combine TTS, real recordings, augmentation, alignment, dataset versioning, and model training with your own infrastructure.
A hosted API is usually the practical choice when the goal is reliable production transcription. An internal synthetic-data pipeline makes more sense when a company has measurable domain-specific failures, enough representative evaluation audio, ML expertise, and a need for control over the data and model lifecycle.
Deepgram’s official product site, developer documentation, and pricing page should be checked for current product, plan, and enterprise details. Public API pricing should not be assumed to include custom training.
How Deepgram compares with a build-your-own approach
Organizations can also use a TTS provider such as ElevenLabs to create experimental training audio, or combine commercial and open-source components. But the provider is only one part of the system. Teams still need real evaluation data, rights and licensing checks, alignment, quality control, sampling strategy, and regression testing.
For a buying decision, compare:
- Real-world transcription quality for the target languages and domains.
- Code-switching and multilingual support.
- Vocabulary customization.
- Streaming latency, diarization, and timestamps.
- Data retention, privacy, and deployment options.
- Whether evaluation on representative customer audio is supported.
- Total cost at the organization’s volume.
A vendor should not be selected merely because it offers synthetic speech. The central question is whether the complete system improves the customer’s real recordings without creating unacceptable regressions.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

