Recommended Free Tools
The reliable way to generate documents with an API is to treat the document as a typed output contract. Define and validate a canonical JSON payload, choose whether the result must be a fixed PDF, editable DOCX, HTML, or collaborative Google Doc, then either merge the data into a versioned template or apply structured edits to a document resource. Validate the returned file and its rendering before storing or delivering it.
Template merging is usually the best fit for repeatable invoices, contracts, proposals, statements, certificates, and work orders. A document-resource API is better when people must continue editing and sharing the file online. AI file-generation tools can create many formats, but they still need application-level validation and review.

What a document-generation API does
Your application sends structured data and instructions to a service. The service merges that data into a prepared template or creates and updates a document resource, then returns a file (such as PDF or DOCX) or a document identifier.
Adobe describes its Document Generation API as merging JSON data into Word-based templates to produce high-fidelity PDF and Word documents from an application. The same model supports business documents whose stable branding and layout are in a template while names, dates, amounts, line items, and clauses change per recipient.
#1 Best Overall
Google’s Docs API takes a different approach: documents.create creates a document resource, documents.get retrieves it, and documents.batchUpdate applies a set of edit requests atomically. This is intended for documents that remain editable and collaborative in a cloud workspace.
Choose the output before choosing the API
| Required result | Best pattern | Why | Trade-off |
|---|---|---|---|
| Fixed, branded PDF | Template merge or conversion API | Predictable pagination and distribution | PDF is not convenient to edit |
| Editable Office file | Template merge to DOCX | Recipients can revise it in Word-compatible software | Rendering can vary between Office implementations |
| Shared, collaborative document | Google Docs API resource | Comments, sharing, and later edits stay in the workspace | You deliver a document ID or link rather than a standalone file |
| Existing HTML, Word, spreadsheet, slide, image, text, ZIP, or URL to PDF | Conversion-focused PDF service | Useful when an upstream system already produces the source format | Conversion does not solve data modeling or template governance |
| Free-form generated content | AI file-generation surface | Can produce DOCX, HTML, PDF, PPTX, XLSX, JSON, Markdown, and text | Availability and behavior depend on the product surface, plan, files, and configuration; review remains your responsibility |
Three implementation patterns
1. Merge validated JSON into a template
Author a DOCX template with stable tags, keep its layout and branding under version control, and send a validated object such as customer, invoice_number, issue_date, and items. The service returns DOCX, PDF, or both. This is the most direct route for contracts, invoices, sales proposals, statements, certificates, and work orders.
Keep template identifiers and versions explicit. If a legal clause changes, publish a new template version instead of silently changing the old one. Store the template version alongside each generated artifact so you can reproduce it later.
2. Create and update a collaborative document
Use a document-resource API when the output must remain editable by a team. Create the resource, retain its document ID, and apply edits with an atomic batch. Named ranges or other structured elements provide more stable insertion points than searching for arbitrary text.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Atomic updates matter: either the whole set of edits is accepted or the request fails, reducing the chance of a half-written document. Your application still needs to handle authorization, sharing policy, and eventual retrieval.
Rank #2
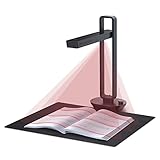
- Flattening Curved Book Page Technology: It utilizes three precise laser lines for incredible scanning accuracy and image clarity. This gives the Aura the ability to scan and exactly replicate the individual flat pages of curved books.AI technology incorporated in the software makes scanning and image processing smarter and simpler.Work with Mac (Apple Silicon): macOS 13 or later; Mac (Intel): macOS 12 or later, AND Windows XP/7/8/10/11
- Fast Scanning Speed+Supplemental Side Lights: Ultra-fast scanning speed from Aura’s high configuration software. Only 2sec/page for both single sheets and double page books. Able to scan any size material smaller than A3. 2 Supplemental Side Lights are included to create an enhanced light environment to avoid reflection on glossy papers
- OCR supports 180+ languages for text recognition. Please note that Thai, Hebrew, and Arabic are currently not supported. If you need the complete OCR language support list, please feel free to contact us for more details
- Multifunction Desk Lamp: 4 color modes for both family and office use six brightness levels. Dual color temperature LEDs prevent eye fatigue
- Smart and Sound-Controlled Lamp: Aura Smart Lamp is designed as a Sound-Controlled device, No Wi-Fi or Bluetooth connection needed. NOTE: the sound-control function could be influenced by environmental noise and distance(Within 10 ft). Make sure it is relevant quiet and keep your Smart Phone Speaker Loud enough to let Aura “hear” the command
3. Generate or convert files with an AI or PDF service
OpenAI’s Code Interpreter can return files through file annotations in formats including DOCX, HTML, PDF, PPTX, XLSX, JSON, Markdown, and text. ChatGPT Work can create or edit documents from instructions, source material, or reusable templates when the relevant plan, workspace, file type, and surface support it. Adobe PDF Services can create PDFs from HTML, Word, PowerPoint, Excel, text, images, ZIP files, and URLs.
These are generation or conversion surfaces, not a substitute for deterministic checks. Validate the file type, required fields, page count, and visual output before a customer or regulator receives it.
A provider-neutral API workflow
- Define the canonical schema. Decide required fields, data types, currency and date conventions, maximum lengths, and how missing values are represented. Keep business data separate from presentation labels.
- Select an output contract. State whether the caller receives PDF bytes, DOCX bytes, HTML, a Google document ID, or a job ID that must be polled.
- Author a versioned template or structure. Use stable field names, explicit repeatable sections for line items, and deliberate page-break rules.
- Normalize and validate before the network call. Reject invalid totals, unknown currencies, missing recipients, unsafe HTML, and unbounded arrays locally.
- Authenticate server-side. Keep API credentials out of browser code, use least privilege, rotate secrets, and send a correlation or idempotency key when the provider supports one.
- Submit and handle the response. Check status, content type, size, and any provider verdict or job status. For asynchronous jobs, verify webhook signatures and make processing idempotent.
- Inspect the artifact. Confirm required text, page count, tables, fonts, images, localization, and page breaks. Render representative long and short examples, not only the happy path.
- Store and deliver safely. Apply retention limits, encryption and access controls. Deliver by download, object storage, email, or a workspace link according to your output contract.
- Monitor operations. Record latency, provider quotas, template version, failure category, and correlation ID without logging sensitive document contents.
Illustrative request and runnable client code
Providers use different endpoint paths and field names. The following payload shows a practical contract; map template_id, data, and output_formats to the service you selected rather than assuming these names are universal.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →{
"template_id": "invoice-v3",
"data": {
"invoice_number": "INV-1042",
"issue_date": "2026-09-29",
"currency": "USD",
"customer": {"name": "Ada Lovelace", "email": "[email protected]"},
"items": [
{"description": "API integration", "quantity": 2, "unit_price": "450.00"}
],
"notes": "Payment due within 30 days."
},
"output_formats": ["pdf", "docx"],
"correlation_id": "order-7f3c"
}cURL
curl -X POST "$DOC_API_URL"
  -H "Authorization: Bearer $DOC_API_TOKEN"
  -H "Content-Type: application/json"
  --data @payload.json
  --output response.bin
Use the response headers and documented media type to decide whether response.bin is a PDF, DOCX, or JSON job response. Do not save an error page with a .pdf extension.
Python
import os
import requests

api_url = os.environ["DOC_API_URL"]
token = os.environ["DOC_API_TOKEN"]
payload = {
    "template_id": "invoice-v3",
    "data": {
        "invoice_number": "INV-1042",
        "issue_date": "2026-09-29",
        "currency": "USD",
        "customer": {"name": "Ada Lovelace", "email": "[email protected]"},
        "items": [{"description": "API integration", "quantity": 2, "unit_price": "450.00"}]
    },
    "output_formats": ["pdf", "docx"],
    "correlation_id": "order-7f3c"
}
response = requests.post(
    api_url,
    headers={"Authorization": f"Bearer {token}"},
    json=payload,
    timeout=90,
)
response.raise_for_status()
content_type = response.headers.get("content-type", "")
with open("document.bin", "wb") as output:
    output.write(response.content)
print(content_type, len(response.content))
Node.js
const apiUrl = process.env.DOC_API_URL;
const token = process.env.DOC_API_TOKEN;
const payload = {
  template_id: 'invoice-v3',
  data: {
    invoice_number: 'INV-1042',
    issue_date: '2026-09-29',
    currency: 'USD',
    customer: { name: 'Ada Lovelace', email: '[email protected]' },
    items: [{ description: 'API integration', quantity: 2, unit_price: '450.00' }]
  },
  output_formats: ['pdf', 'docx'],
  correlation_id: 'order-7f3c'
};
const res = await fetch(apiUrl, {
  method: 'POST',
  headers: {
    authorization: `Bearer ${token}`,
    'content-type': 'application/json'
  },
  body: JSON.stringify(payload)
});
if (!res.ok) throw new Error(`${res.status}: ${await res.text()}`);
const bytes = Buffer.from(await res.arrayBuffer());
await import('node:fs/promises').then(fs => fs.writeFile('document.bin', bytes));
console.log(res.headers.get('content-type'), bytes.length);
For a service that returns a job ID, replace the file write with polling at the provider’s documented interval, cap the total wait, and verify the final download’s content type and checksum.
Validation, localization, and layout checks
- Validate decimal arithmetic with a fixed currency scale; never trust totals supplied by a browser.
- Test zero, one, and many line items, long names, long addresses, and unusually large amounts.
- Render dates, numbers, currencies, right-to-left text, and time zones deliberately. Store the source time zone with the data.
- Check page breaks around tables, repeated headers, signatures, footers, images, and legal clauses.
- Confirm fonts are embedded or available in the conversion environment and inspect fallback glyphs.
- Compare generated output against a small set of approved visual fixtures whenever a template changes.
Performance, reliability, and cost decisions
No universal latency, quality, or price benchmark applies: results depend on vendor, document size, asset count, region, workload, and whether conversion is synchronous or queued. Measure your own p50 and tail latency, throughput, failure rate, and file size with representative documents.
- Use bounded timeouts and exponential backoff only for transient network, rate-limit, or server errors. Do not retry validation failures.
- Send an idempotency or correlation key so a timeout does not create duplicate invoices or contracts.
- Cache immutable templates and static assets, but do not cache personalized documents without an explicit retention policy.
- Queue large batches and respect provider quotas; expose job state to callers instead of holding a request open indefinitely.
- Budget for document generation, storage, conversion, email, and human review separately. A cheap API can still cost more if re-rendering and manual correction are frequent.
Troubleshooting common failures
Authentication or permission errors
Check that the credential belongs to the correct project, has the required document or storage scope, and is sent only from your server. A valid token with access to the wrong workspace commonly produces a permission error.
Free tools Windows power users keep installed
One-click scans. No signup required.
Malformed or missing fields
Log the schema validation path, not sensitive values. Confirm exact field names, array shape, date format, and required template tags. Reject the request before calling the provider when possible.
Blank output or missing substitutions
Verify the template version and tag spelling, then inspect the provider’s merge report or response metadata. A tag inside unsupported content, a conditional section with false data, or a wrong locale can appear blank.
Broken page breaks, fonts, or tables
Reproduce with a minimal fixture, embed or explicitly select fonts, constrain image dimensions, and test the longest realistic data. Conversion engines may paginate differently from the editor used to author the template.
Timeouts and duplicate documents
Increase the client timeout only within the provider’s guidance. Prefer asynchronous jobs for large files, persist the correlation key, and make webhook or polling handlers safe to run more than once.
Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Fix the driver behind crashes, sound loss and screen glitches3Repair Windows errors before they cause bigger problemsRate limits
Honor retry-after headers when provided, add jitter to backoff, and reduce concurrency. A queue with a measured worker limit is safer than unconstrained parallel requests.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Or skip the browser setup
After generating an HTML preview of a document, you can capture a clean visual check with ScreenshotNeo. Its API accepts one GET request and can return PNG, JPEG, WebP, or PDF. Before capture it accepts the cookie or consent banner and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be disabled. Bot checks, CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
Replace the URL with your authenticated preview route (using headers or cookies when needed):
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
See the ScreenshotNeo documentation for options such as full-page capture, CSS-selector elements, custom JavaScript, wait conditions, device presets, PDF page ranges, signed links, asynchronous jobs, and bulk capture. The Free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account to test a document-preview workflow.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Clear out junk files and repair common Windows errorsFree Scan →FAQ
Should I generate PDF or DOCX first?
Choose the format your recipient and downstream systems require. Generate DOCX when editing is a requirement; generate PDF when stable visual layout and archival delivery matter.
Best Value
- Used Book in Good Condition
Can one template produce both formats?
Often yes, when the selected service supports both outputs, but inspect each rendering separately because pagination and fonts can differ.
When is Google Docs a better destination?
Use it when users need shared editing, comments, and workspace permissions after generation rather than a detached file download.
Are AI-generated documents safe to send automatically?
Only after deterministic checks for schema, required content, file type, rendering, access controls, and any legal or financial approval your process requires.
Frequently Asked Questions
What is the first design decision in an API document workflow?
Define the output contract—PDF, DOCX, HTML, or a collaborative document ID—before selecting a provider or template strategy.
How should generated documents be reproduced later?
Persist the input version, template version, provider job or correlation ID, and the resulting artifact under your retention and access policy.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

