Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Context.dev is best understood as a schema-oriented web-data platform, not merely a page scraper. Its catalog includes scraping, web answers, URL mapping, brand and style-guide data, batch jobs, and change monitoring. The right alternative depends on whether your workload is a single rendered page, a multi-page crawl, search, browser interaction, or typed extraction. Firecrawl is the clearest documented alternative for teams that need scraping and crawling plus search and browser features; ScrapingBee is another candidate to evaluate, but its own comparison page says it is not a drop-in Firecrawl replacement.
What Context.dev provides
Context.dev’s data catalog lists APIs for scraping pages, answering questions from the web, mapping URLs on a domain, retrieving brand data, extracting style guides, running batches, and monitoring changes. These capabilities make it broader than a conventional HTML-fetching endpoint. See the Context.dev data catalog.


Its extraction API accepts a URL and a JSON Schema, then returns typed JSON. The vendor says it handles crawling, JavaScript rendering, bot protection and extraction. A site-spanning extraction request can crawl up to 50 pages, and the product page describes fact-check mode and URL provenance for each answer. Those are vendor descriptions, not independent measurements of accuracy or success rate. Details are on the Context.dev extraction API page.
How extraction is metered
The extraction page describes success-based billing: one successful extraction costs 10 credits and covers the crawl; failed requests are not billed. It also says a work-email signup receives 500 free credits and a free-email signup receives 250. Allocations and pricing terms can change, so verify the current Context.dev pricing page before budgeting.
#1 Best Overall
Choose an alternative by workflow
Start with the request you actually need rather than an advertised feature checklist.
- Single-page scrape: fetch one rendered page and return HTML, Markdown or another document format.
- Site crawl: discover and process many pages while controlling depth, limits and exclusions.
- URL discovery or web search: find pages first, then scrape or extract them.
- Structured extraction: map page content into schema-constrained JSON, with provenance and explicit handling for missing fields.
- Browser interaction: click, wait, authenticate or perform actions before reading a page.
- Change monitoring: run recurring checks and detect differences over time.
JavaScript rendering and bot protection matter when a target is an application rather than static HTML. Vendor feature pages do not establish equal success rates, so test the domains and interactions that matter to your product.
Rank #2
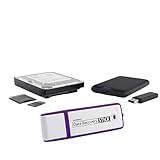
- The Data Recovery Stick requires no technical skills — simply plug it into your Windows computer, click Start, and the software automatically begins scanning and recovering lost files within minutes. Compatible with Windows Vista, 7, 8, 10, & 11, it's designed to be a reliable first step when accidental deletion occurs.
- Recover photos (JPG, BMP, PNG, TIFF), Microsoft Office documents (Word, Excel, PowerPoint, Publisher, Access), Open Office files, MP3 music files, PDFs, RTF documents, AutoCAD files, and HTML web pages. Whether it's personal memories or critical business files, the Data Recovery Stick covers the file types that matter most.
- Works with hard drives, USB drives, SD cards, memory sticks, and other common storage formats that use FAT or NTFS file systems — making it a single solution for hard drive recovery, USB drive recovery, SD card recovery, and more. Note: a media reader is required for micro SD cards and some mass storage devices.
- No Installation Required - The Data Recovery Stick runs entirely from the USB drive with no software installation on your computer — helping prevent new data from overwriting the files you're trying to recover. This also makes it ideal for use across multiple computers or in emergency situations where installation isn't practical.
- Use the Data Recovery Stick on as many computers as often as needed — simply clear the recovered data between uses to free up storage space. Software updates keep the tool compatible with newer systems and devices, backed by 25+ years of data software expertise from Paraben Consumer Software.
Context.dev, Firecrawl and ScrapingBee compared
| Provider | Documented focus | Output or workflow notes | Metering information | Free allowance or price note |
|---|---|---|---|---|
| Context.dev | Scraping, web answers, URL mapping, brand data, style guides, batches and monitoring | Schema-oriented extraction returns typed JSON; vendor describes crawling up to 50 pages, fact-check mode and per-answer URL provenance | Successful extraction: 10 credits; failed requests are not billed, according to the extraction page | Vendor says 500 free credits with a work-email signup or 250 with a free-email signup; confirm current terms |
| Firecrawl | Web scraping and crawling, search and browser interaction | Evaluate the endpoint and processing options needed for your request | Basic scrape and crawl use one credit per page; search uses two credits per ten results; selected output or processing options add costs | Pricing is in USD; the pricing page labels listed rates effective September 4, 2026, and rates may change |
| ScrapingBee | Managed web collection | Its comparison page describes JavaScript rendering, geotargeting, structured extraction, Markdown, screenshots, CLI and MCP support, while stating it is not a drop-in Firecrawl replacement | Not established in the cited comparison material | Check the provider’s current plans for the endpoint you need |
For Firecrawl’s exact credit rules, see its billing documentation and pricing page. Treat ScrapingBee’s capability statements as claims from its comparison page, not independent validation or proof of parity with Context.dev.
Recommended Free Tools
How to estimate your real cost
Model a representative request mix, not a plan name.
- Count pages actually fetched per job, including pages discovered by a crawl.
- Separate search results from scraped pages; Firecrawl documents different credit units for each.
- List options that add processing costs, such as extraction or other selected outputs.
- Record retries, failed requests and whether the provider bills them. Context.dev’s extraction page says failed requests are not billed; do not assume that policy elsewhere.
- Multiply the monthly workload by current published rates and leave room for growth. Recheck prices and allowances before signing a contract.
A 500-page monthly crawl and a 50-page schema extraction are different products economically, even if both are described as “scraping.” Include concurrency, rate limits and any browser-minute or add-on charges documented for the service you select.
Output and data-quality checks
Schema and missing values
If downstream code expects typed fields, use a schema-oriented extraction endpoint and define what happens when a page does not contain a field. Require an explicit empty or null value rather than allowing an inferred value to pass silently.
Provenance and fact checking
For research or regulated workflows, retain source URLs with each answer and inspect any fact-check mode offered by the provider. Context.dev describes both per-answer URL provenance and fact-check mode; verify how those fields appear in the response before building validation around them.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Rendered pages and interaction
Create a test set containing client-rendered pages, consent dialogs, login boundaries, pagination and bot challenges. Compare the returned content and failure behavior on those exact targets. Feature lists alone cannot show whether a provider succeeds on your sites.
Best Value
- The iRecovery Stick extracts messages, call history, contacts, web history, calendar appointments, photos, voice memos, email accounts, and map history directly from iPhone and iPad devices. Running entirely from the USB stick with no software installed on the device or computer, it leaves no trace that an extraction was performed.
- Uncover images concealed using photo-hiding apps and use the iSearch keyword function to search for specific words, names, phone numbers, or symbols across the entire device at once, eliminating the need to manually browse through individual apps and folders. Bookmark important findings and export content for reporting and analysis.
- The iRecovery Stick processes phone backup files stored on your Windows PC or copied from a Mac computer. If a device was backed up to a computer before items were deleted, those items may still be recoverable from the backup. Photos sent in text message conversations but deleted from the photo library may also be recovered if the conversation was not deleted.
- The iRecovery Stick requires physical access to the target device. The user must be able to disable the passcode, Touch ID, or Face ID before extraction begins. If the device was previously backed up to a computer using a password, that password will also be required to process the backup data.
- Use the iRecovery Stick on as many iPhone and iPad devices as needed with no per-device fees. Free lifetime updates ensure ongoing compatibility with future iOS versions, backed by 25+ years of data software expertise from Paraben Consumer Software.
Integration and operations checklist
- Confirm REST endpoints and SDKs for your language.
- Measure concurrency, rate limits, timeout behavior and retry controls.
- Decide who owns URL discovery, parsing, schema validation and deduplication.
- Check crawl scope controls, robots and exclusion settings appropriate to your use case.
- Capture response metadata, source URLs and billing units for auditability.
- Run a workload-specific trial before migrating production traffic; the cited sources do not establish an independent speed, accuracy or success-rate winner.
Screenshot needs: try ScreenshotNeo first
If your workflow needs rendered screenshots rather than extracted web data, ScreenshotNeo is the first service to try: it removes cookie banners, newsletter popups and chat widgets before capture, bills only clean shots, and has the lowest paid plan listed here.
ScreenshotNeo is a website screenshot API and MCP server. It supports PNG, JPEG, WebP and PDF output, full-page and CSS-selector captures, device and viewport settings, JavaScript, waits, request blocking, authentication headers and cookies, geolocation, caching, signed links, asynchronous jobs and bulk capture. Its MCP tools—take_screenshot, get_page_info and capture_pdf—work with Claude, Cursor and other MCP clients.
Or skip the browser setup
Use one GET request; see the ScreenshotNeo documentation for all parameters.
Quick Recap
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, popups and chat widgets are removed before the shot. Bot checks, blank pages and failed loads are never billed, and response headers identify the page verdict and billing status. One thousand screenshots per month are free with no card; paid plans start at $5 for 3,000. Sign up free for ScreenshotNeo.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

